H3 Long Video Prompting
H3 Long Video Prompting
Turn a shot idea longer than 15 seconds into a segment-by-segment plan that actually renders.
MiniMax H3 generates 15 seconds at a time. A 40-second piece is not a prompt-writing problem — it is an engineering problem: split the action, choose the right input mode per segment, hold consistency, handle the seams. This skill does that work and hands you something you can submit.
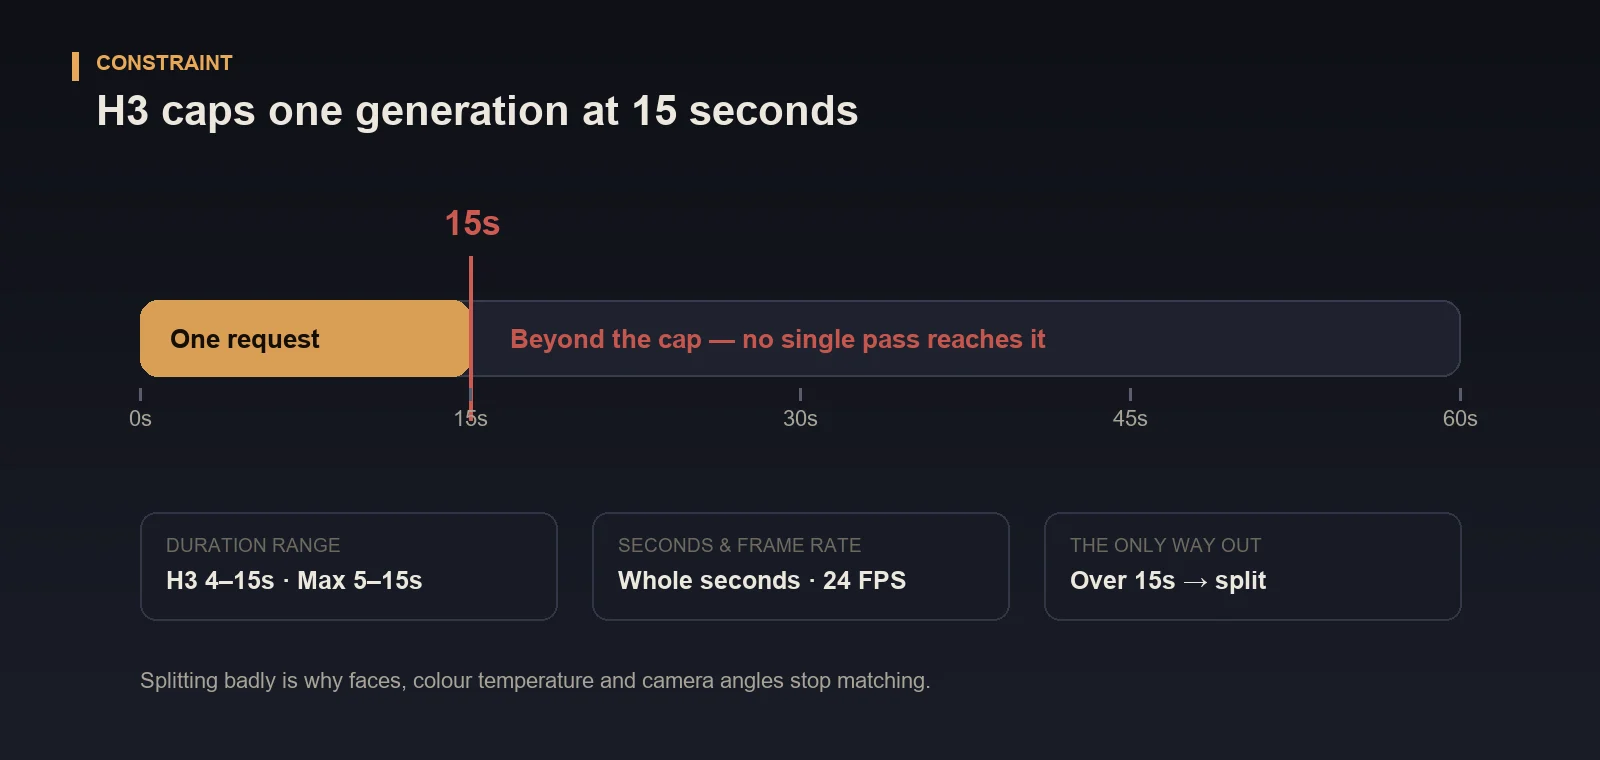
The constraint you can't prompt around
| Spec | Value |
|---|---|
| H3 | 4–15 s |
| H3 Max | 5–15 s |
| Duration | whole seconds only |
| Frame rate | 24 FPS |
There is no prompt trick that gets past 15 seconds. You split. How well you split decides whether the finished piece is watchable — and the usual failure isn't "not knowing how to split", it's ending up with a different face, a different colour temperature and a camera that doesn't match across cuts.
Three steps: split → choose mode → lock anchors
1 · Split
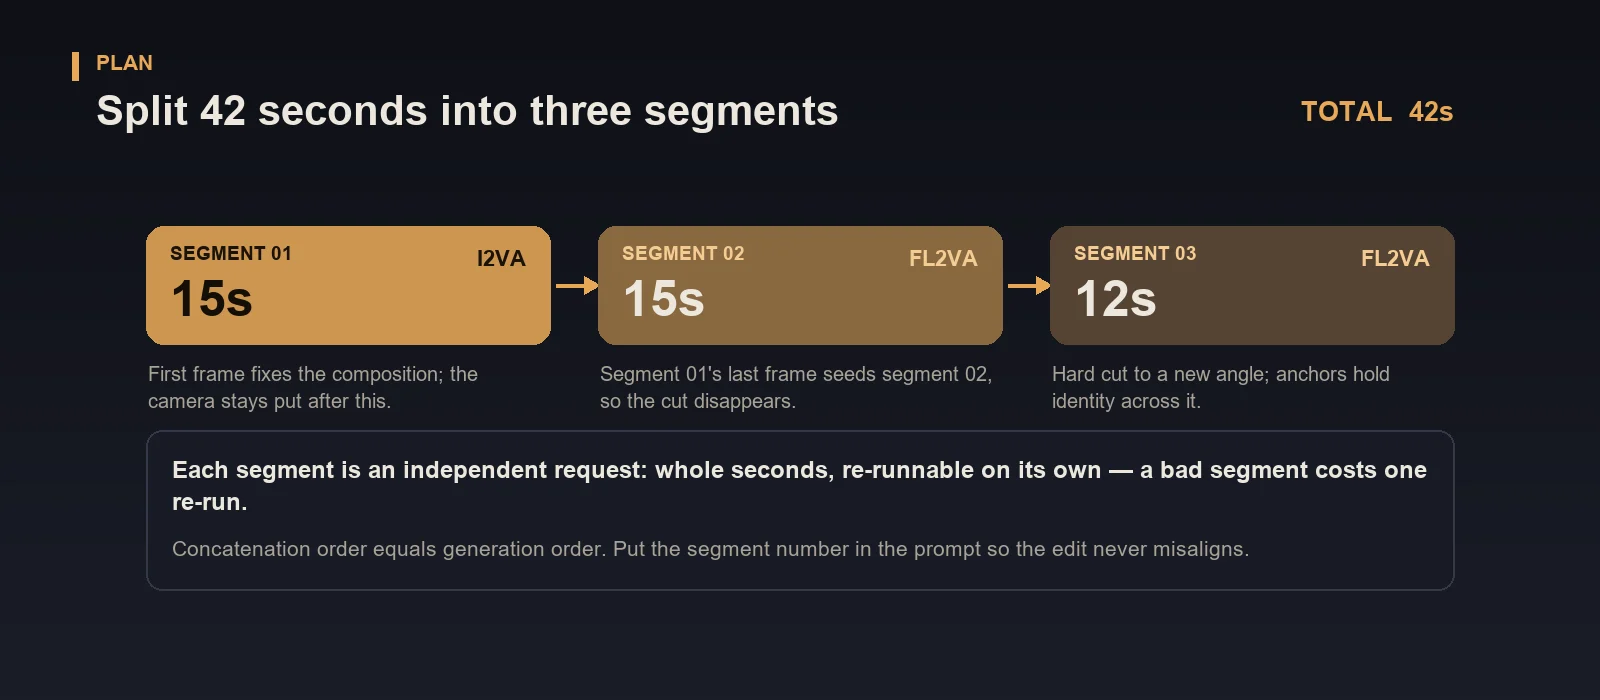
- Each segment ≤ 15 s, whole seconds, cut on a beat of action — not in half by the clock
- Each segment is an independent request: re-runnable on its own, so a bad segment costs one re-run
- Number the segments inside the prompt, so the edit can't misalign later
2 · Choose the mode
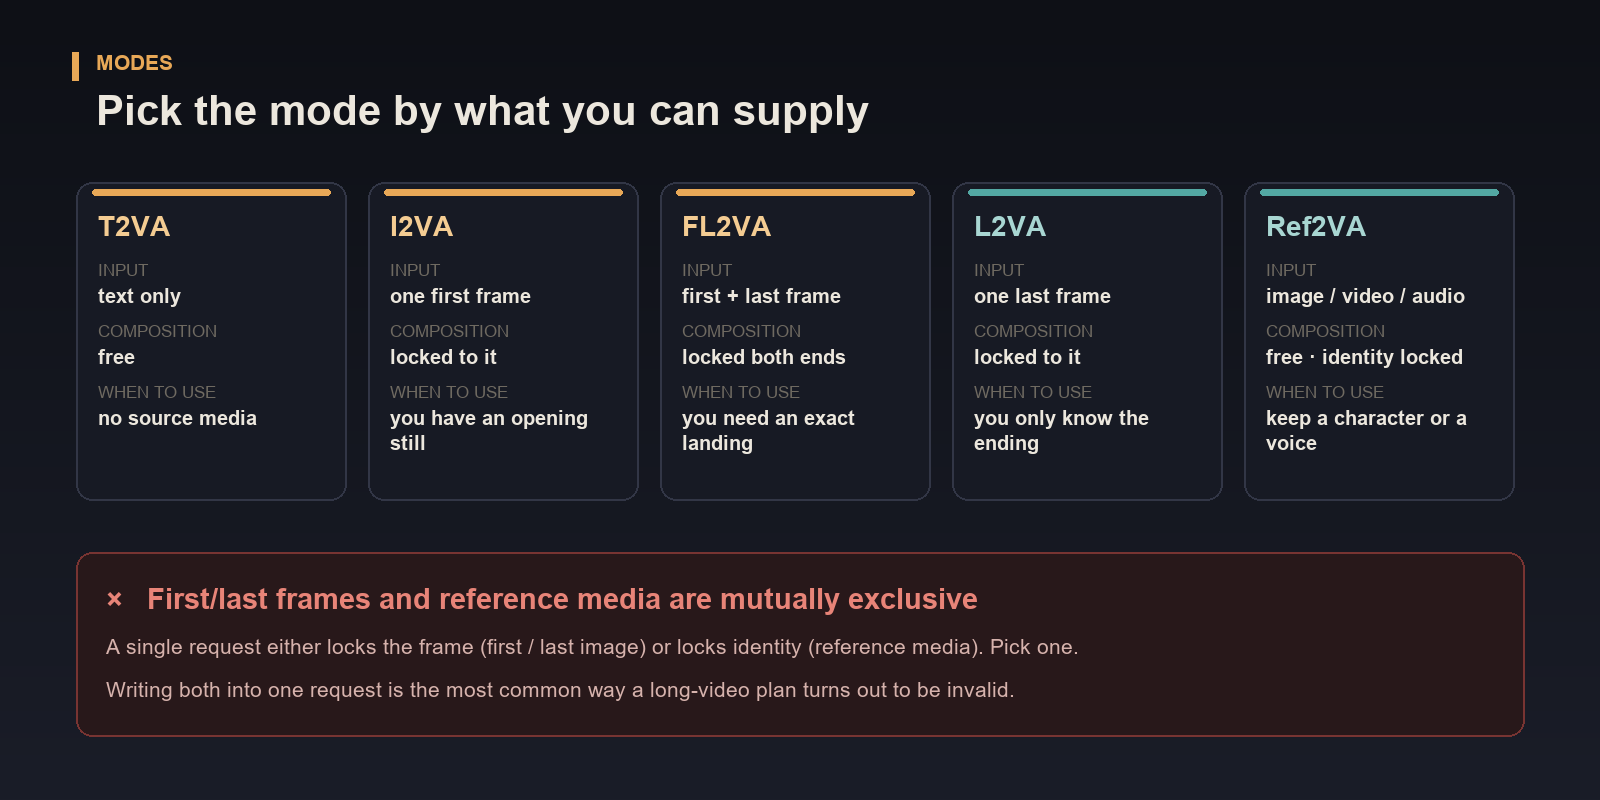
| Mode | Input | Composition | Use when |
|---|---|---|---|
| T2VA | text only | free | no source media, prompt only |
| I2VA | one first frame | locked to it | you have an opening still and need it to move |
| FL2VA | first + last frame | locked at both ends | you need an exact landing, e.g. a specific closing pose |
| L2VA | one last frame | locked to it | you only know how it ends |
| Ref2VA | image / video / audio reference | free, identity locked | you must keep a face, a style or a voice |
⚠️ The most common mistake: first/last frames and reference media are mutually exclusive. A single request either locks the frame, or locks identity. Writing both into one request produces an invalid request, no matter how good the prose is.
3 · Lock anchors, then write per segment
Consistency does not come from describing the face again in every segment. It comes from one anchor block reused verbatim:
- Face, features, hair, wardrobe, accessories — written as fixed sentences, never reworded
- Colour temperature, key-light direction, lens length — fixed, not drifting per segment
- Aspect ratio, frame rate, banned items (subtitles / watermark / extra people) — stated once in the global settings
The model has never seen this character before, every single time. So the anchors travel with every segment.
Seams: chain the tail frame, or hard cut
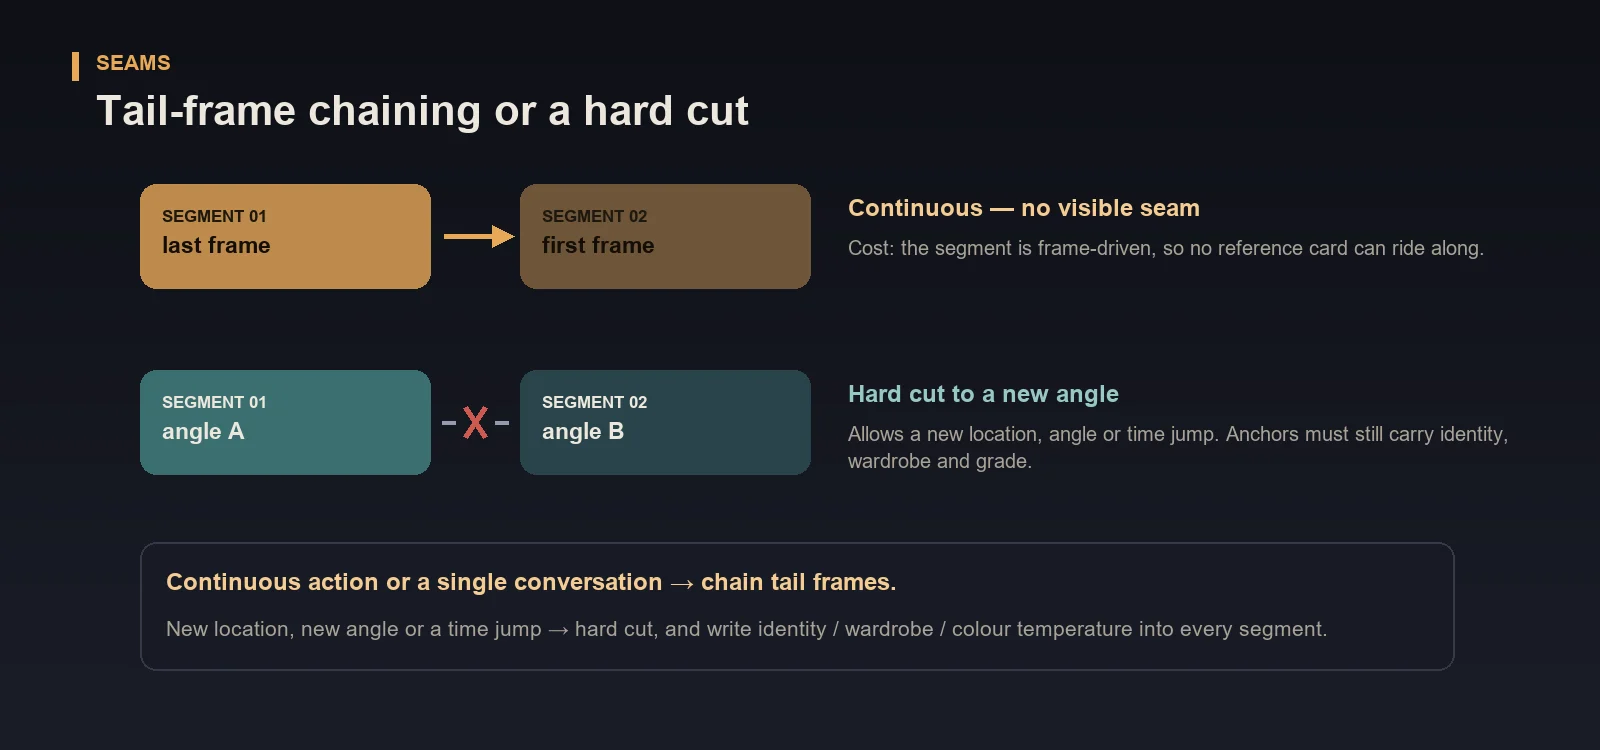
| Situation | Use | Cost |
|---|---|---|
| Continuous action, one conversation | Tail-frame chaining — segment 01's last frame becomes segment 02's first frame | That segment is frame-driven, so no reference card can ride along |
| New location, new angle, time jump | Hard cut | Identity and grade must be carried by the anchors |
Get this wrong and you get one of two accidents: a visible flash where the action should have been continuous (you hard-cut it), or a dead-static camera where the angle should have changed (you chained the frame).
What you get
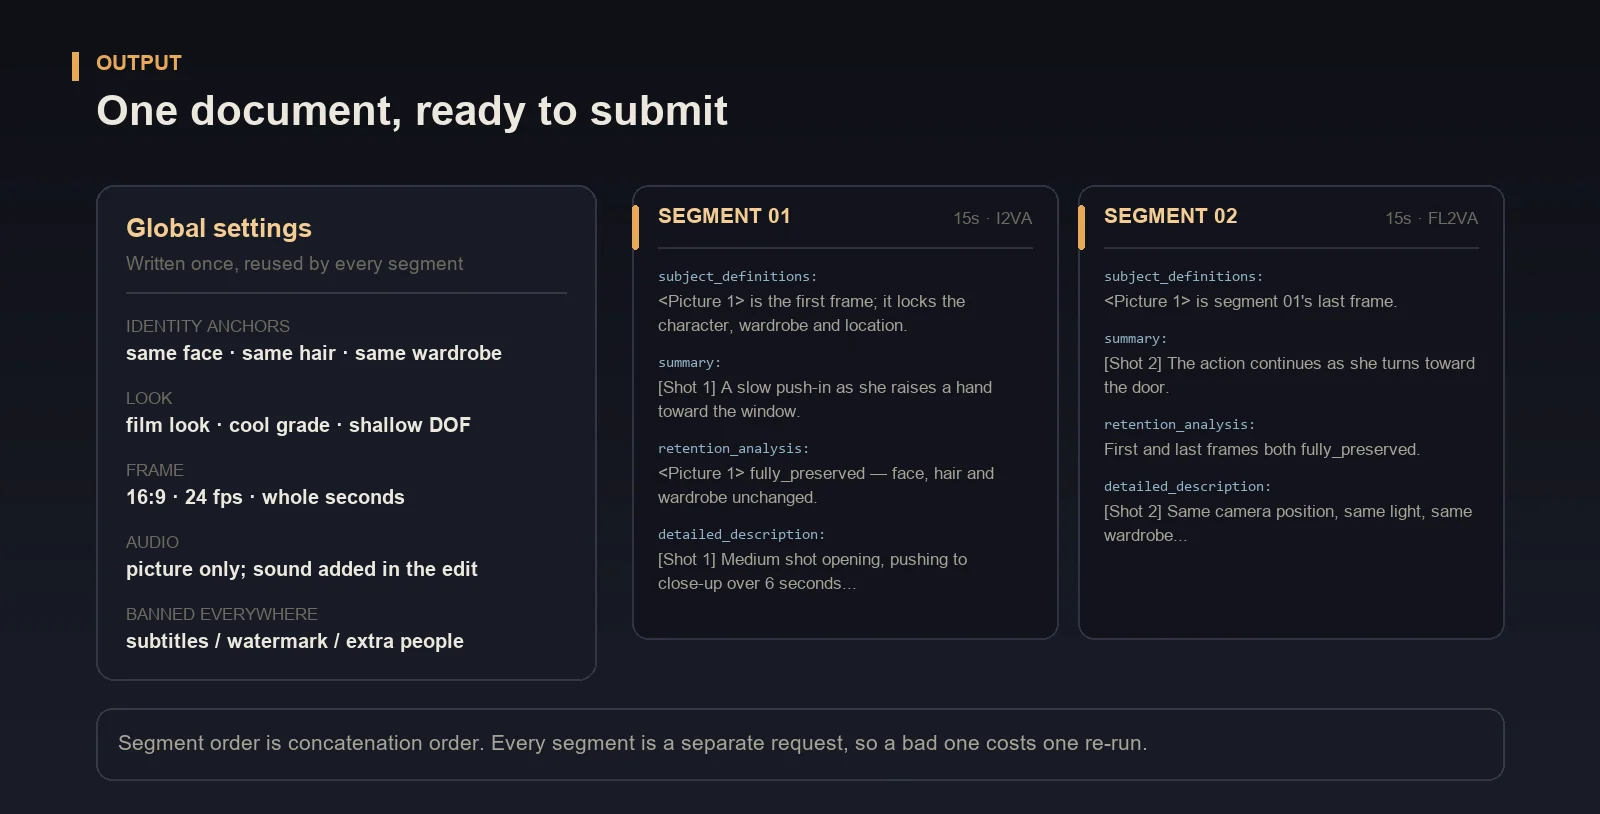
One Markdown document, in two parts:
- Global settings — identity anchors, look, frame, audio, banned items. Written once, reused by every segment.
- One complete prompt per segment — written in H3's six-part structure, ready to paste:
subject_definitions:
<Picture 1> is the first frame; it locks the character, wardrobe and location.
summary:
[Shot 1] A slow push-in as she raises a hand toward the window.
retention_analysis:
<Picture 1> fully_preserved — face, hair and wardrobe unchanged.
detailed_description:
[Shot 1] Medium shot opening, pushing to close-up over 6 seconds...
overall_soundscape:
Quiet room tone, fabric movement.
non_diegetic_music:
N/A
A 42-second example
| Seg | Length | Mode | Anchor | Content |
|---|---|---|---|---|
| 01 | 15 s | I2VA | first frame sets composition | opening, character enters |
| 02 | 15 s | FL2VA | chained from 01's last frame | continuous action, camera unchanged |
| 03 | 12 s | FL2VA | hard cut to a new angle | ending, identity held by anchors |
Three independent generations that concatenate into one continuous 42 seconds.
When not to use it
- Single shot, ≤ 15 s — no splitting needed. Use
h3-prompt-writing; this extra step is pure overhead. - You just want one prompt, no stitching — same as above.
- You need precise lip sync — that's digital-human mode's job, not something segment planning can solve.
Hard constraints at a glance
| Constraint | Value |
|---|---|
| Segment length | H3 4–15 s / H3 Max 5–15 s, whole seconds |
| Frame rate | 24 FPS |
| First/last frames vs reference media | mutually exclusive in one request |
| Aspect ratio | I2VA / FL2VA / L2VA inherit it from the input image; it can't be overridden |
| Cross-segment consistency | carried by the global anchor block, not by luck |
FAQ
Q: Can I just write one 30-second prompt?
No. The model caps at 15 seconds. A 30-second prompt gets you a 15-second clip, or a failure.
Q: Why can't I give a last frame and a reference image?
The platform treats those as mutually exclusive branches. If you genuinely need "same identity plus a continuous frame", split instead: chain frames for the continuous segment, use reference media for the segment where the camera changes.
Q: Do I have to rewrite the whole prompt for every segment?
No. Change the subject sentence — what happens in this segment — and carry the anchor block over untouched.
Q: Can segments be generated in parallel?
Reference-driven segments can. Frame-chained segments must be serial, because the next segment's first frame is an artefact of the previous one.
Q: What about audio?
Audio generated per segment will always break at the seams. Either render silent and dub in the edit, or cut on breaths and downbeats — never mid-word.
v2.0 · Compiled from the MiniMax H3 official docs, the H3 API schema published by fal.ai / Atlas Cloud / EmpirioLabs, and the Scenario H3 handbook.