HookScan | Video Hook Analyzer, First 8 Seconds
Measure the first seconds of your video, then get a tighter opening back
Most hook tools give you a score or a predicted drop-off curve and leave the editing to you. HookScan measures what actually happens in the first 8 seconds of your video, marks each check PASS or FIX with the change in seconds, and returns two re-cut versions of the video: one with the dead start and long pauses removed, and one that opens on your strongest line.
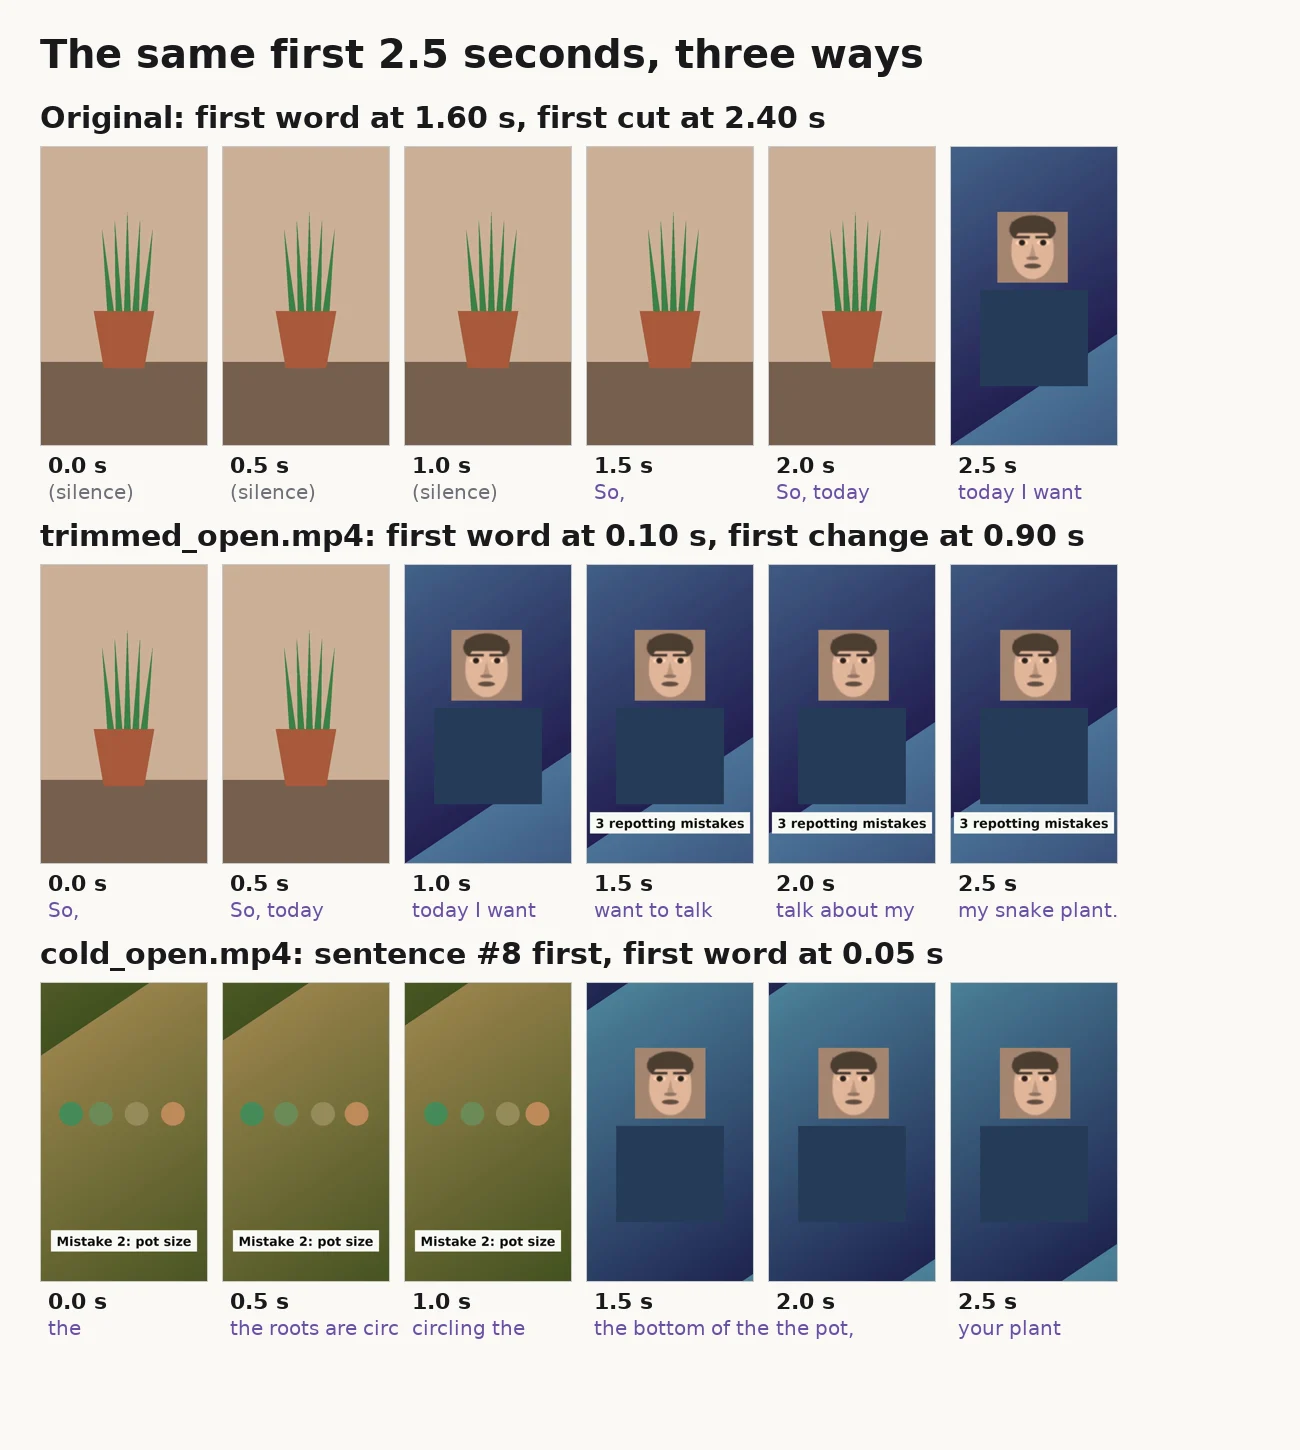
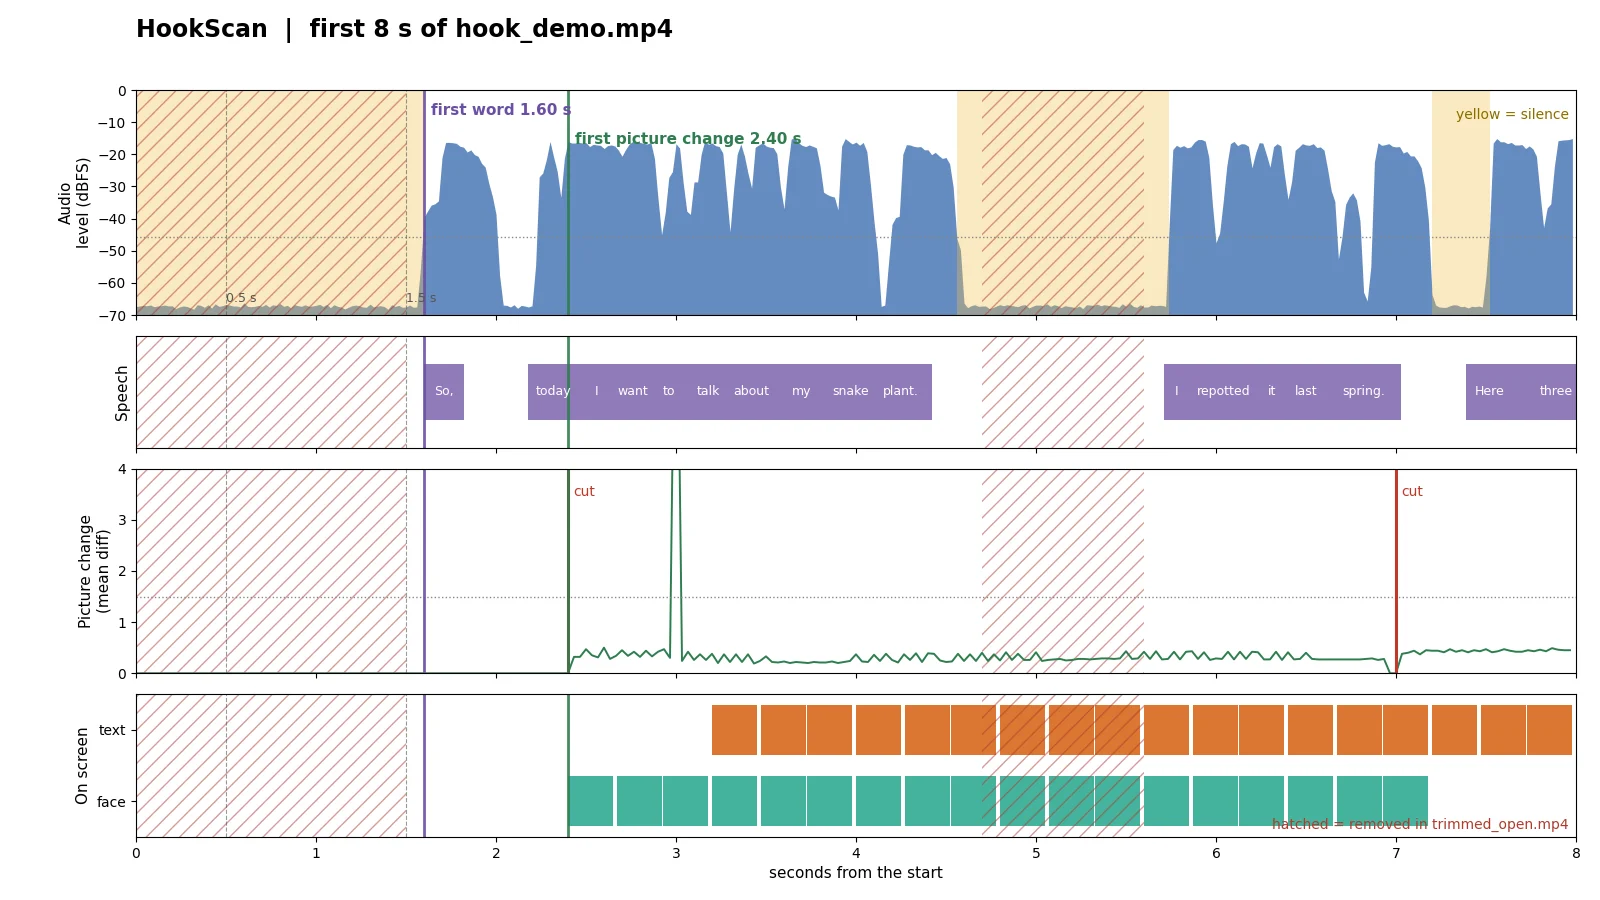
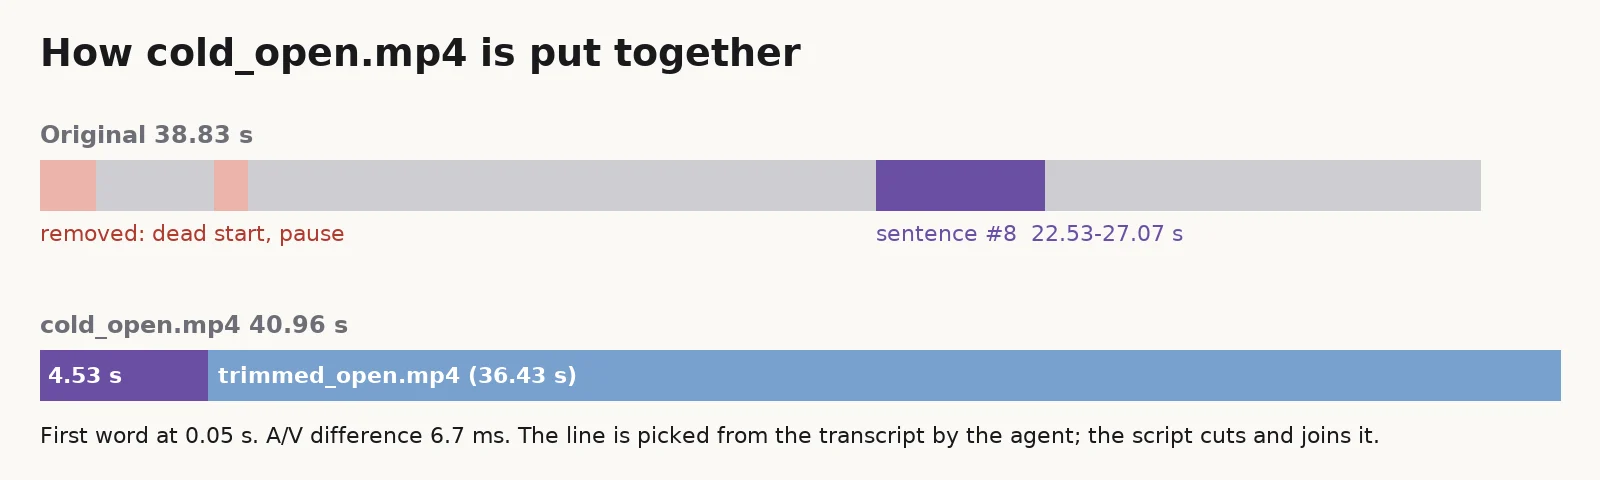
In the test video the first word comes at 1.60 s on a still frame. trimmed_open.mp4 brings it to 0.10 s; cold_open.mp4 starts with a line from 22.53 s.
How you use it
Here is my video. Check the opening and give me a tighter version.
Upload the file and send one message. No install, no settings. It runs in the Capafy cloud.
What you get back
| File | What it is |
|---|---|
hook_report.md |
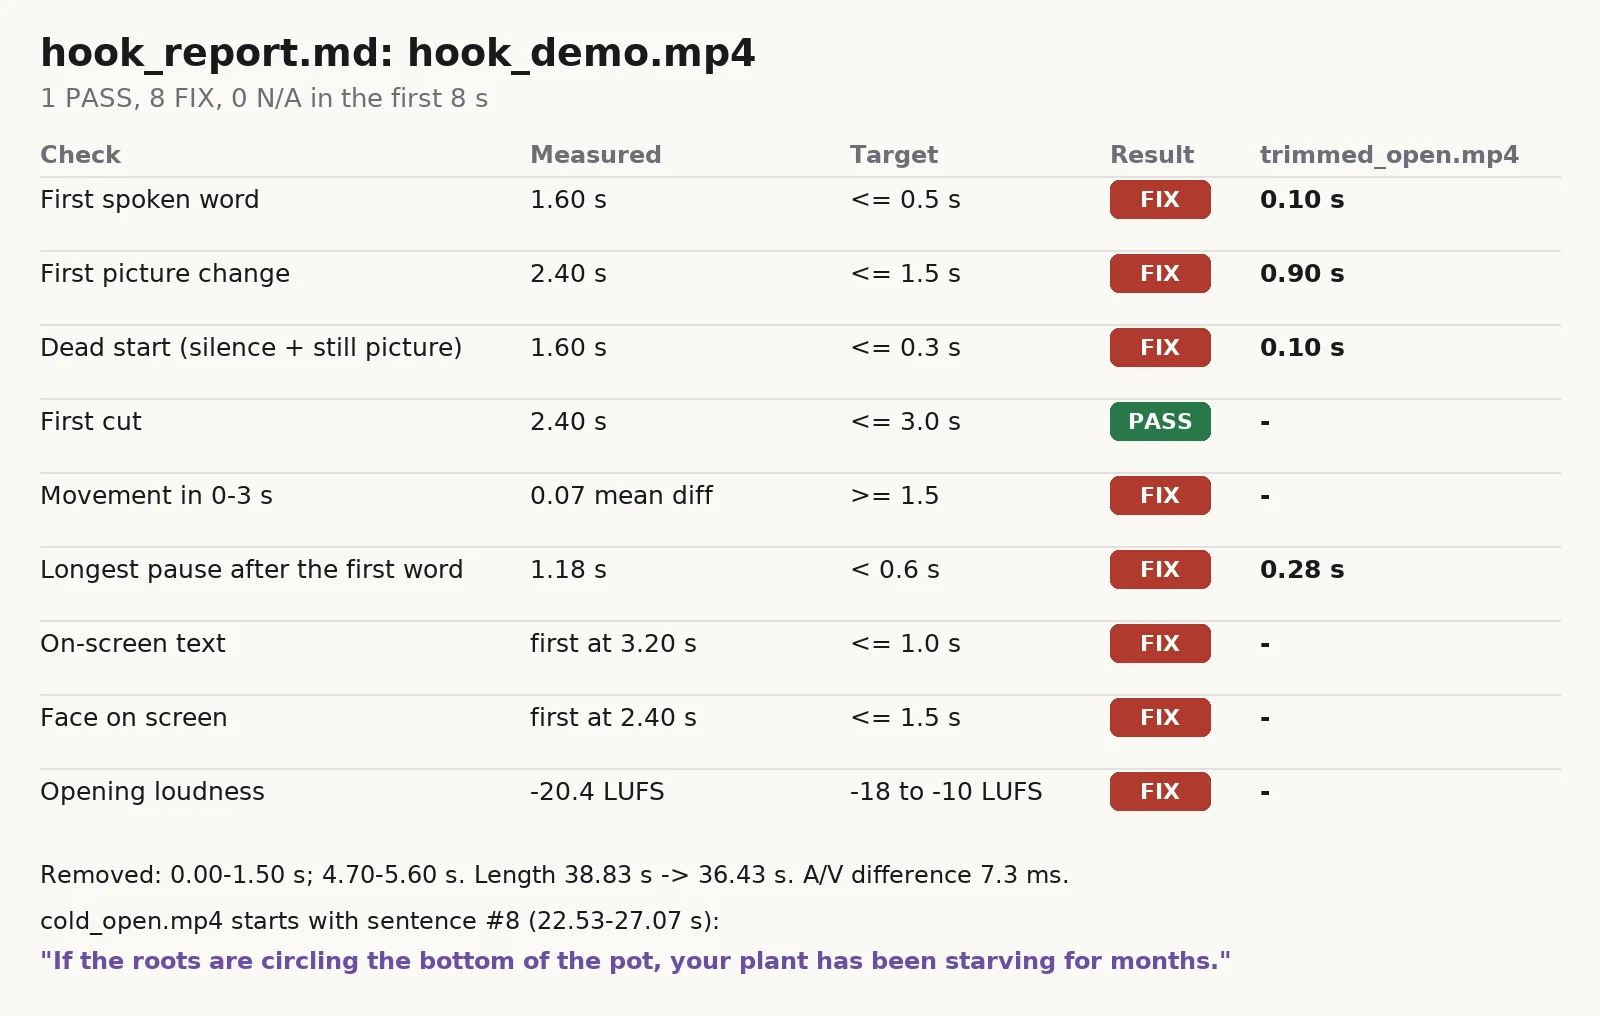
Every check with the measured value, the target, PASS or FIX, and the change in seconds. An event list of the first 8 s, a before/after table for the trimmed file, and loudness |
hook_timeline.png |
0-8 s chart: audio level and silences, each spoken word, picture change and cuts, text and faces on screen. Removed parts are hatched |
trimmed_open.mp4 |
The full video with the silent, still start and long pauses in the opening removed. Speech is never cut. Everything after the last edit is your original timing |
cold_open.mp4 |
One sentence from later in your video moved to 0 s, followed by trimmed_open.mp4 |
transcript_first30s.txt |
The sentences of the first 30 seconds with start and end times |
The checks
| Check | Target |
|---|---|
| First spoken word | by 0.5 s |
| First picture change (cut, movement, text or face appearing) | by 1.5 s |
| Dead start (silence and a still picture together) | 0.3 s or less |
| First cut | by 3.0 s |
| Movement in 0-3 s | mean frame difference 1.5 or more |
| Longest pause after the first word | under 0.6 s |
| On-screen text | by 1.0 s, for viewers on mute |
| Face on screen | by 1.5 s (N/A when no face appears) |
| Opening loudness | -18 to -10 LUFS and not quieter than the rest of the video |
These targets are rules of thumb for short-form openings, not platform rules. HookScan does not predict retention or views.
How the cold open is chosen
The scripts transcribe the whole video and list every sentence that starts after the first 3 seconds. The agent reads that list and picks one line that works on its own at the start: a concrete claim, a problem the viewer can check, a number or a direct question. It skips greetings, "today I want to talk about" lines and lines that depend on an earlier setup. The script then cuts that sentence on the audio edges, puts it at 0 s and joins the trimmed video after it. The report says which line was used and why. Ask for a different sentence or give your own time range and it re-renders.
How it works
- Speech. faster-whisper (base model) transcribes the audio with word times; the first word's start is refined on the audio level.
- Picture. PySceneDetect finds cuts on every frame; frame differences measure movement; RapidOCR finds on-screen text and OpenCV finds faces about 4 times per second.
- Sound. Silences come from the 20 ms audio level; loudness from ffmpeg's EBU R128 meter.
- Re-cut. Picture and sound are cut on the same frame edges and rendered in separate passes, then joined. In tests the audio and video ends differ by under 12 ms.
How long it takes
Measured in a 2 CPU test container like the Capafy sandbox:
| Video | Report, timeline, trimmed_open.mp4 | cold_open.mp4 |
|---|---|---|
| 39 s vertical 720p | 14 s | 2 s |
| 9 min 43 s vertical 1080p | 3 min 17 s | 7 s |
The first run in a new workspace adds about 30 s to download the speech model.
Requests and plans
Every message you send uses 1 request from your plan. One message is enough for a full run (report, timeline, both videos). Asking for another cold-open line is one more message.
| Plan | Price | Requests |
|---|---|---|
| Daily | $2.99 | 5 per day |
| Weekly | $7.99 | 10 per week |
| Monthly | $19.99 | 30 per month |
What it does not do
- It does not predict retention, views or watch time, and it does not score your content.
- It does not add captions, music, zooms or text. The report tells you where to add them, in seconds.
- It does not write new lines. The cold open only uses a sentence you already said.
- It does not download from links. Upload a file you have the right to use.
- Videos over 10 minutes are not accepted. Videos larger than 1920 px on the long side come back at 1920 px.
FAQ
Will it cut my speech?
No. trimmed_open.mp4 only removes the silent, still start and pauses of 0.6 s or more in the first 8 seconds, keeping 0.15 s on each side. A pause with a cut or new text inside it is left alone.
Is the sound still in sync?
Yes. Sound and picture are cut on the same frame edges. In the smoke test the ends of the audio and video tracks differ by 7.3 ms (trimmed) and 6.7 ms (cold open).
What if my video has music under the voice?
Silence detection then finds no silence, which is correct, and nothing is removed for pauses. First-word timing still comes from the transcript.
What if there is no speech?
The word checks show N/A and there is no cold open. The picture, text, face and loudness checks and trimmed_open.mp4 still run.
Which languages work?
The speech model detects the language and transcribes it; the report is in English and the agent answers in your language.
Does my video leave the workspace?
No. The video, transcript and results stay in the workspace. The only network use is installing Python packages and downloading the speech model once.
API externas
PyPI (pypi.org, files.pythonhosted.org) · Hugging Face (huggingface.co, *.hf.co)