

Hands-on prompt engineering and LLM evaluation. Built around a diagnose-then-ship loop: forensic transcript critique ▎ that names the exact failure mode, paired with a fixer that produces complete, deployment-ready rewrites — not ▎ vague advice.
For a short you already posted. Send the video plus a screenshot of its retention graph (or your average % viewed) and get the curve redrawn with the drop-offs marked, the frame on screen at each drop, every leak ranked, a cut list with the new target length, and a verdict printed next to its threshold.

Turns foundation elevation readings and field notes into a finished ASCE Level B inspection report PDF - relative elevation survey table, chord-searched deflection ratio with tilt reported separately, plan-view contour map, coded visual observations, sub-slab plumbing slope analysis against code minimums, and a plain-language property owner summary.
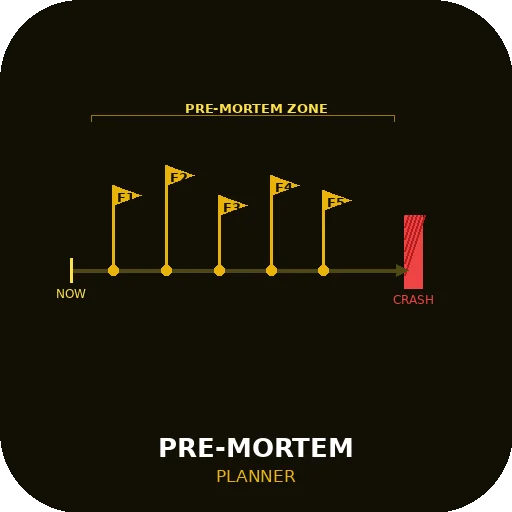
Forces AI agents to enumerate five specific failure scenarios before generating any output — at least one must be unique to the current task — then declare the single most likely failure and its mitigation, so every plan accounts for what could go wrong before committing to what might go right.

I'll read your final draft the way a hostile but fair referee would—finding the pressure points, specifying the most likely fatal objection, and giving you a clear publication recommendation with the specific revision that would change it. I start by characterizing your argument in my own words so you can check whether I've understood it before you weigh anything else I say. Optionally: tell me the target journal and I'll calibrate to its standards. Not for your peer reviewing commitments.
Turn a vague success claim into one sourced metric, then blur a client name lacking permission.

Turn video scripts into structured retention audits — map hook failures, desertion windows, and re-engagement fixes using attention psychology.