Agent Shield — AI Agent Security Preflight
Audit AI agents, Skills, MCP configurations, tool permissions, and coding-agent setups for prompt injection, excessive agency, credential exposure, data leakage, unsafe code execution, supply-chain risks, memory risks, missing approval controls, and runaway autonomy. Get a calibrated Security Score, Audit Confidence, evidence-backed findings, remediation steps, verification checks, and residual-risk analysis.
#エンジニアリング#分析#生産性
評価
さらに評価が必要です
販売数
0
利用方法
ダウンロード
Agent Shield
AI Agent Security Preflight
Audit your AI agent, Skill, MCP configuration, or coding-agent setup before installation, publication, or deployment.
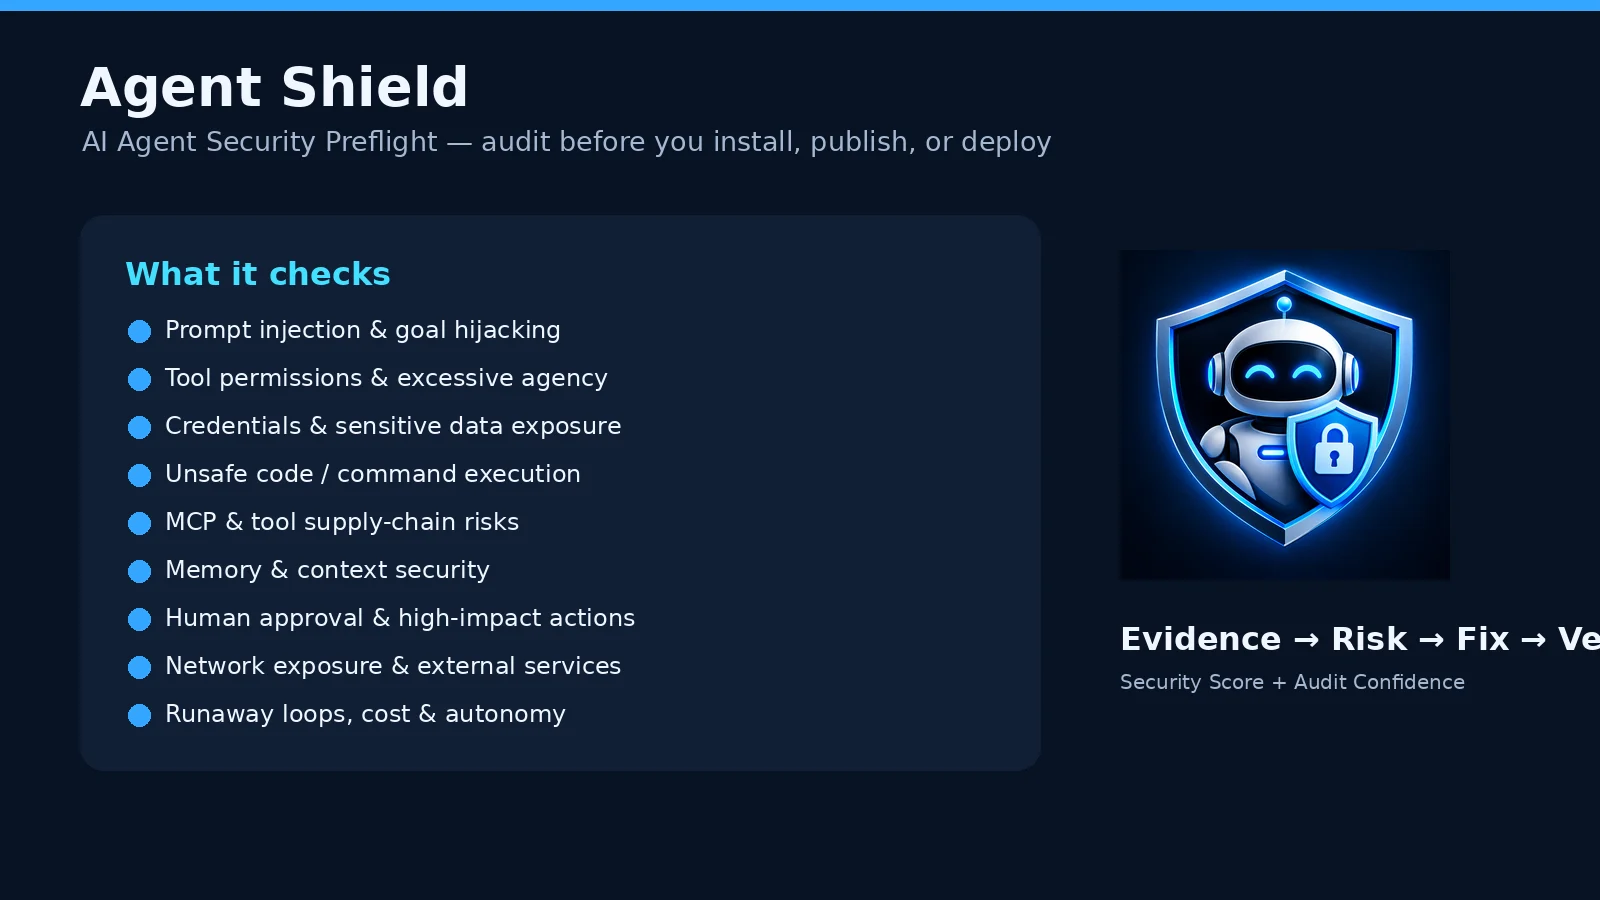
What Agent Shield Checks
Agent Shield reviews the security boundaries that matter when an AI system can use tools, access data, execute actions, or interact with external services.
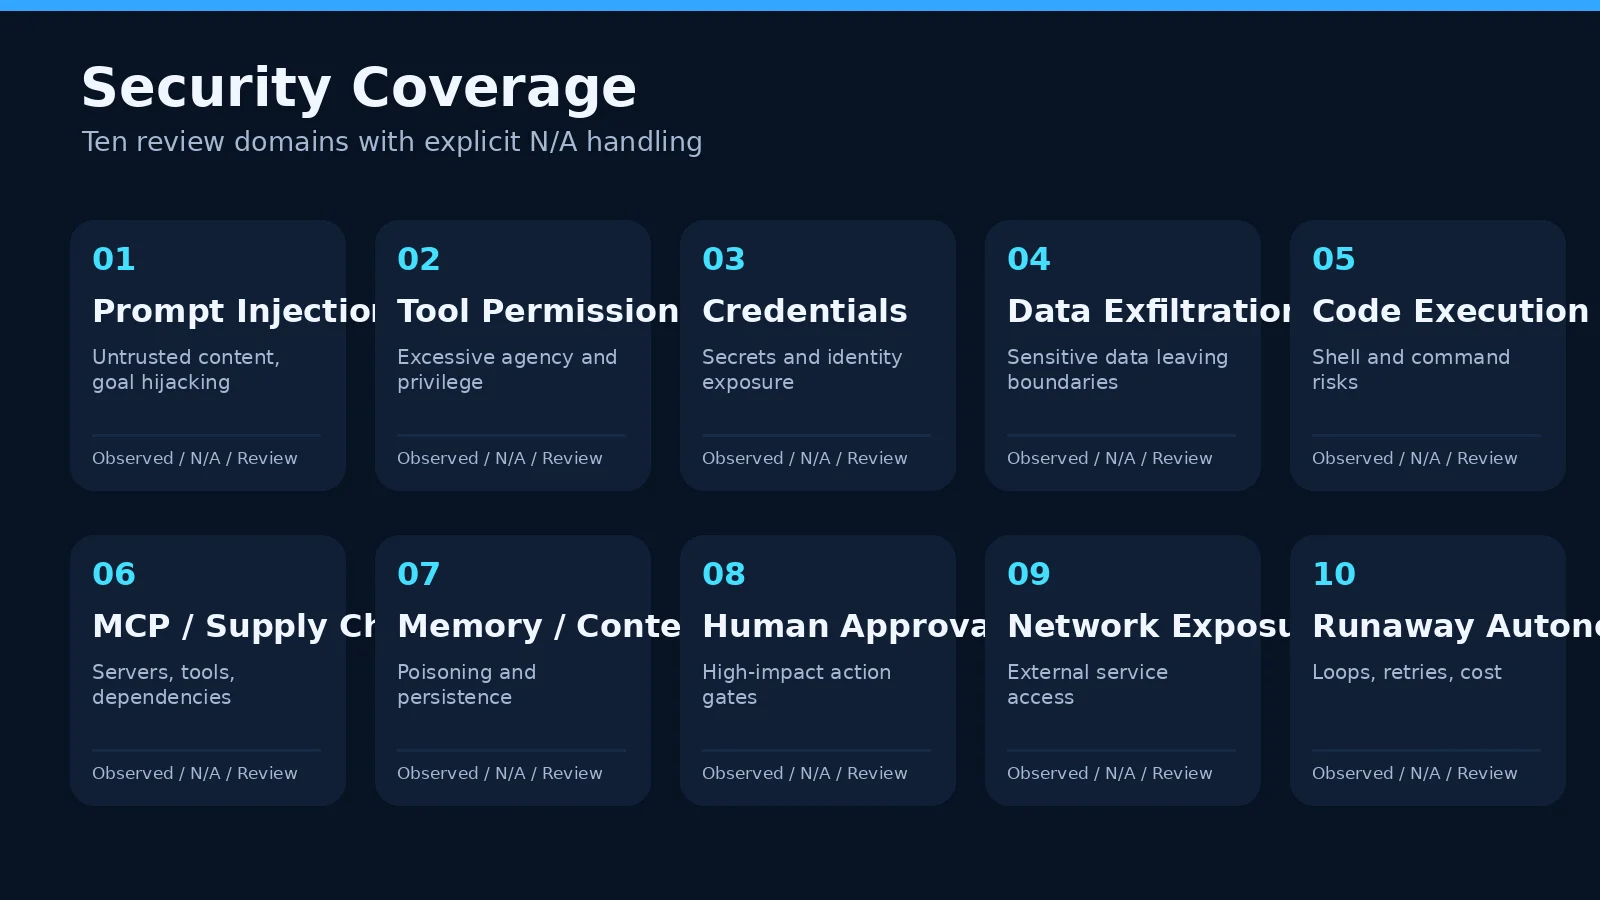
Security Domains
- Prompt Injection & Goal Hijacking
- Tool Permissions & Excessive Agency
- Credentials & Identity
- Sensitive Data & Exfiltration
- Code & Command Execution
- MCP & Tool Supply Chain
- Memory & Context Security
- Human Approval
- Network Exposure
- Runaway Autonomy
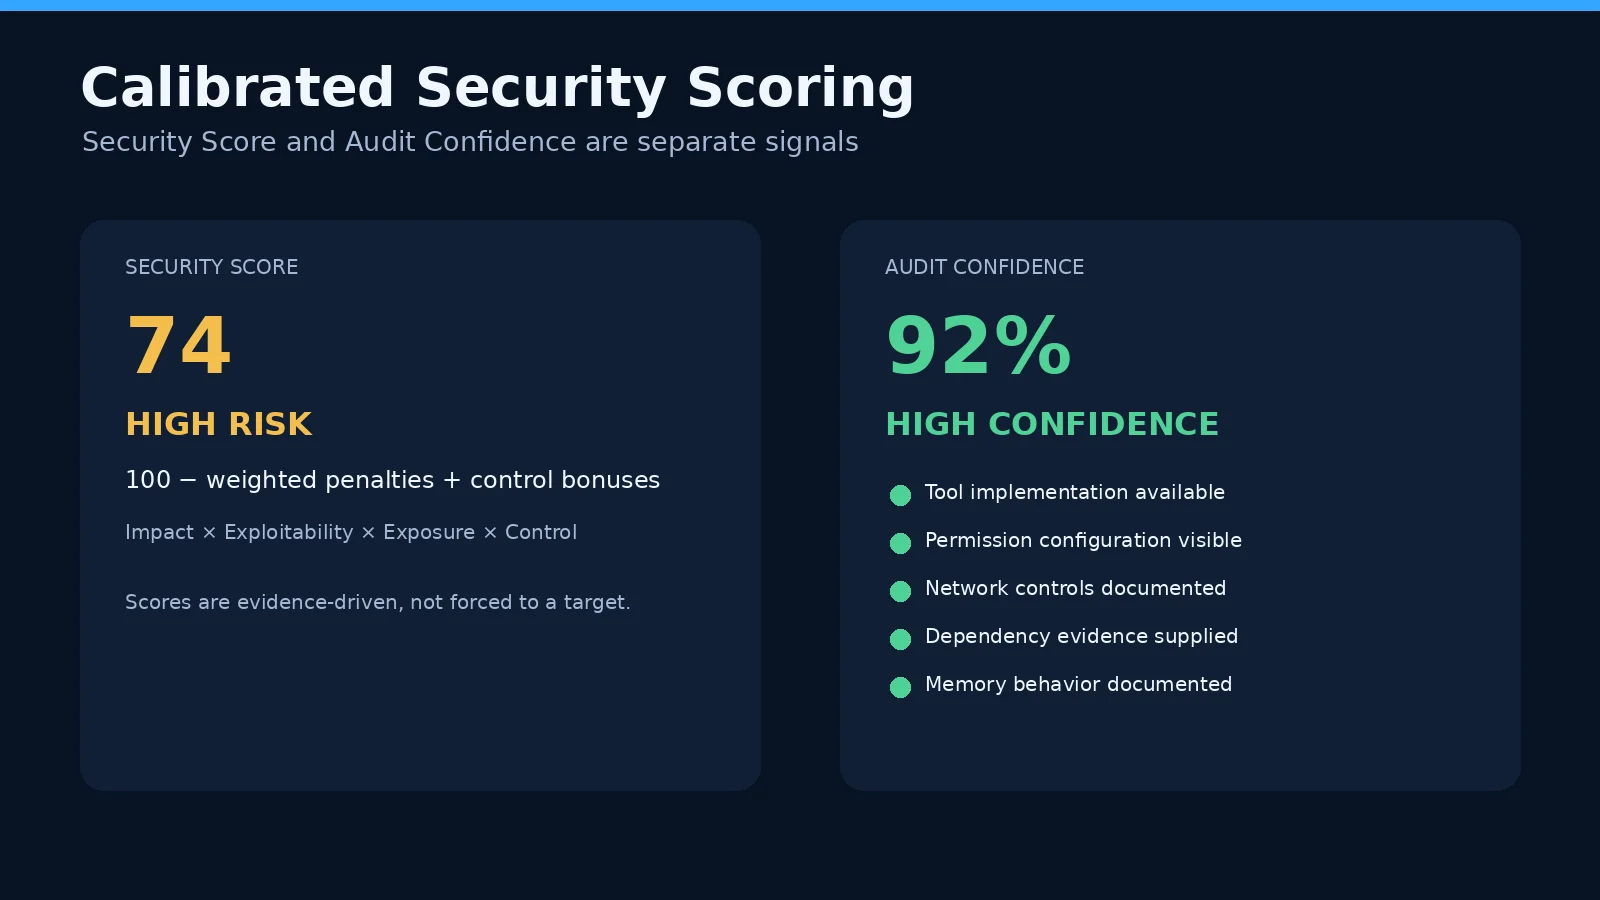
Security Scoring
Agent Shield produces two separate signals:
- Security Score — how risky the observed configuration is.
- Audit Confidence — how complete and reliable the available evidence is.
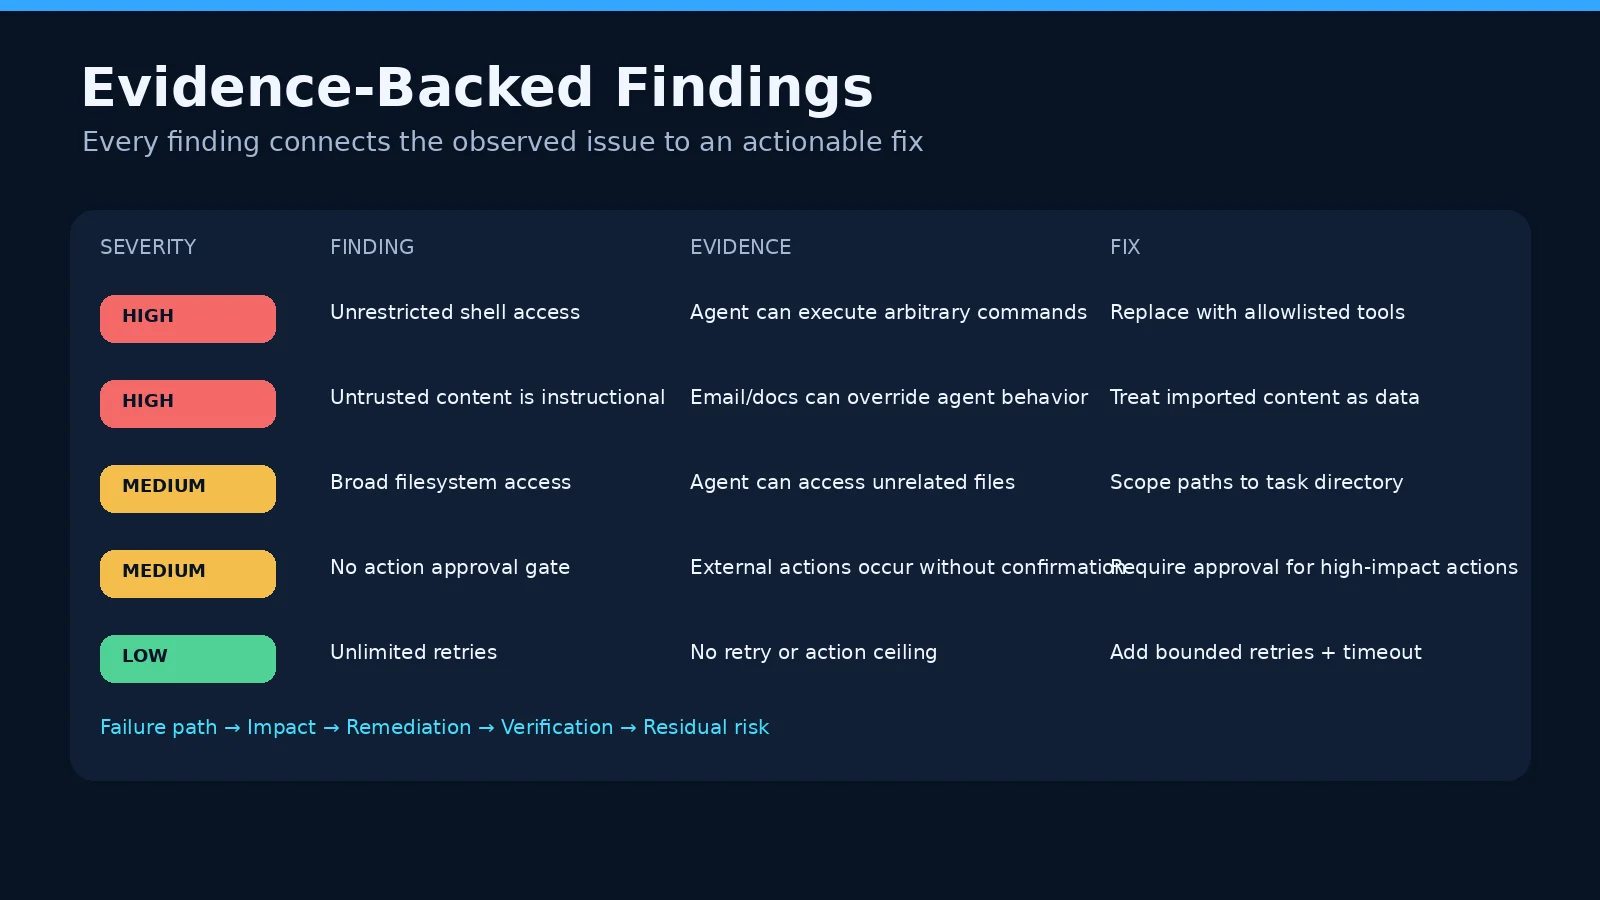
Evidence-Backed Findings
Each finding should explain:
- What was observed
- Evidence
- Severity
- Why it matters
- Failure path
- Recommended fix
- Verification
- Residual risk
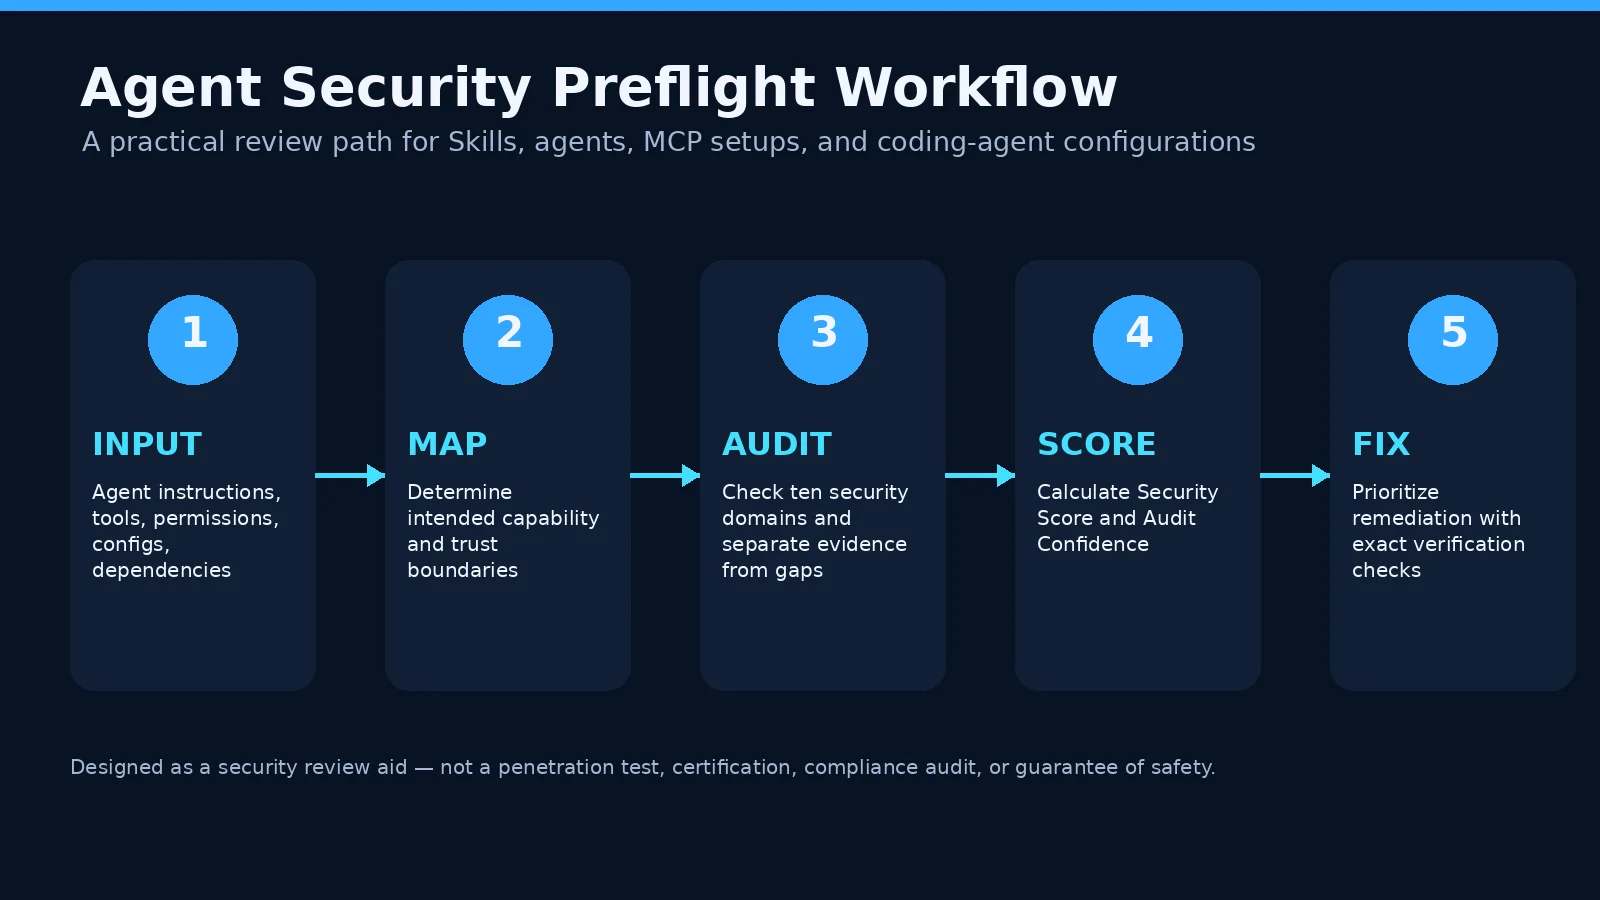
How It Works
- Provide the agent configuration and available evidence.
- Determine the intended capability and trust boundaries.
- Audit the relevant security domains.
- Calculate the Security Score and Audit Confidence.
- Prioritize fixes and verification checks.