

MCP & Agent Skill Trust Brief
MCP & Agent Skill Trust Brief
A context-aware install risk brief for MCP servers, AI agent skills, coding-agent plugins, and similar GitHub repositories.
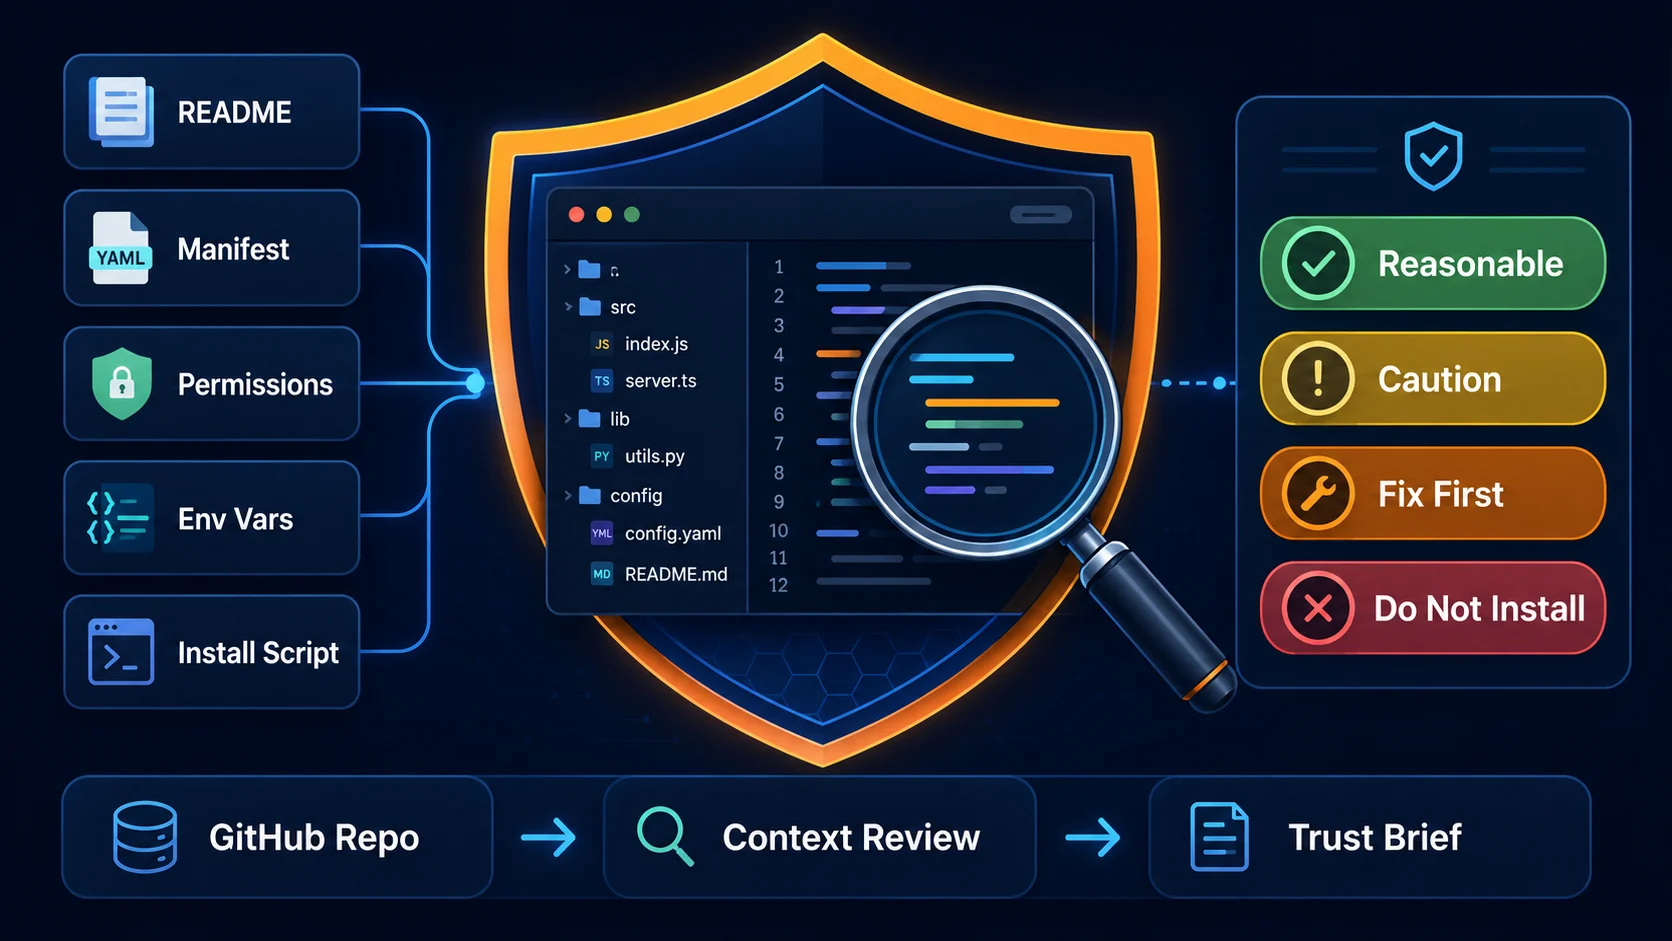
Paste a GitHub URL, README, SKILL.md, MCP manifest, package metadata, source snippets, scanner output, or repo zip. The Agent reviews the tool in context and tells you whether it is reasonable to install, connect, publish, or fix first.
What You Get
- Trust verdict based on reviewed scope
- Coverage and evidence summary
- Permission map
- Severity and confidence for every finding
- CONSISTENT / UNDOCUMENTED BUT PLAUSIBLE / INCONSISTENT / UNVERIFIED classification
- OWASP LLM / Agentic AI / MITRE ATLAS-style risk mapping when relevant
- README or manifest warning patch
- Least-privilege notes
- 7-day hardening plan
- Final install decision
Why It Is Different
Many scanners flag suspicious patterns in isolation.
This Agent first reads the repository's stated purpose, then compares it against actual files, permissions, network calls, env var access, install scripts, and tool definitions.
That means broad permissions are not automatically treated as malicious when they match the purpose, but undocumented or inconsistent behavior is still surfaced with evidence.
Best For
- Developers installing MCP servers
- Teams reviewing AI agent skills
- Builders publishing coding-agent plugins
- Users checking GitHub repos before connecting them
- Maintainers who want practical hardening notes
Output Sections
- What this is
- Coverage and evidence
- Trust Verdict
- Permission Map
- Findings
- What I could not verify
- If you proceed
Important Note
This is a static, context-aware trust review. It does not execute repository code, install dependencies, run postinstall scripts, or claim full security certification.


