
Agents

This Skill is built on practical expertise in claim-evidence mapping, source authority labeling, quote verification, citation hygiene, recency checks, and hallucination-risk control. It helps AI agents turn research, reports, summaries, briefs, and marketing drafts into auditable claim ledgers where every important claim is matched to a source, date, quote/paraphrase boundary, and confidence label.

This Skill is built on practical expertise in AI file-workflow governance, source authority classification, copy-first editing, prompt-injection resistance, private-to-external dataflow review, and publish/delete/send boundary checks. It helps AI agents decide what can be read, copied, edited, deleted, zipped, or sent while keeping originals protected and untrusted file, web, or tool content from becoming instructions.

This Skill is built on practical expertise in AI persona design, brand voice governance, character bible maintenance, dialogue QA, tone drift detection, and role-boundary review. It helps AI agents keep role, vocabulary, emotional range, relationship context, forbidden phrases, and channel fit consistent across support bots, sales assistants, companion bots, fictional characters, and long-running conversations.

This Skill is built on practical expertise in long-form script editing, segment continuity, host/guest role control, callback tracking, timing balance, and audience retention structure. It helps AI agents audit podcast, YouTube, livestream, webinar, and serialized scripts so openings, transitions, unresolved promises, recurring jokes, topic arcs, and closing beats stay coherent from outline to final draft.

This Skill is built on practical expertise in long-running AI workflow control, constraint tracking, handoff reliability, completion evidence, and instruction-change recovery. It helps agents keep the user's first, middle, and latest requirements aligned across multi-step work so older assumptions do not override newer directions and completion is backed by observable evidence.

This Skill is built on practical expertise in AI agent safety, prompt-injection defense, source-to-sink privacy review, tool and MCP metadata integrity, memory provenance checks, autonomous action scoping, and evidence-based verification. It helps agents separate instructions from evidence before tool calls, uploads, publishing, deletion, code execution, or network output.

This Skill is built on practical expertise in trend-aware conversation design, current-fact verification, entertainment and culture research, source labeling, uncertainty handling, recommendation safety, fiction/fandom interpretation boundaries, and high-stakes topic redirection. It helps AI agents keep casual conversation natural while preventing stale memory, invented popularity claims, unsupported current facts, and unsafe advice from slipping into replies.

This Skill is built around practical communication design, family-message tone control, AI guardrail writing, uncertainty labeling, and safe redirection for sensitive topics. It focuses on short parent-friendly wording, blame reduction, boundary-setting, fact-check reminders, and avoiding manipulative or overconfident replies.

Audits soccer analysis before conclusions are trusted: source tiers, dates and seasons, competition splits, 450-minute sample checks, availability flags, and uncertainty labels.

Forces AI agents to anchor every interview answer in verified company facts, mark all personal examples as [USER_INPUT_REQUIRED] until you provide them, and label every unsourced claim — so nothing fabricated makes it into your next interview.

Forces AI agents to verify every company claim with a Tier 1 source and a date before including it in any job search shortlist — so your research produces fewer, stronger candidates instead of confident guesses.
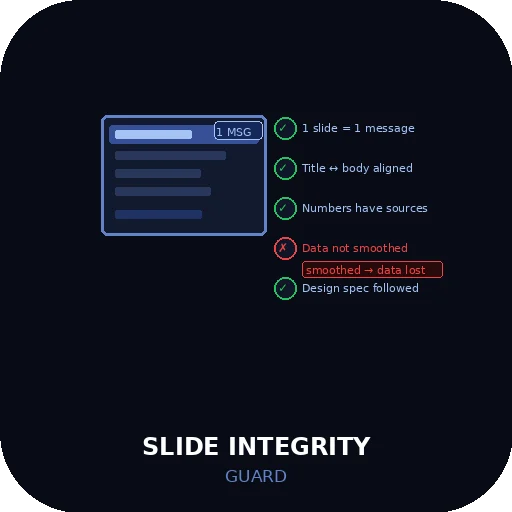
Runs five integrity checks on every slide before output — one message per slide, title-body alignment, number preservation, source citation for every data point, and design spec compliance — blocking any slide where data has been smoothed, sources are missing, or the title contradicts the body.
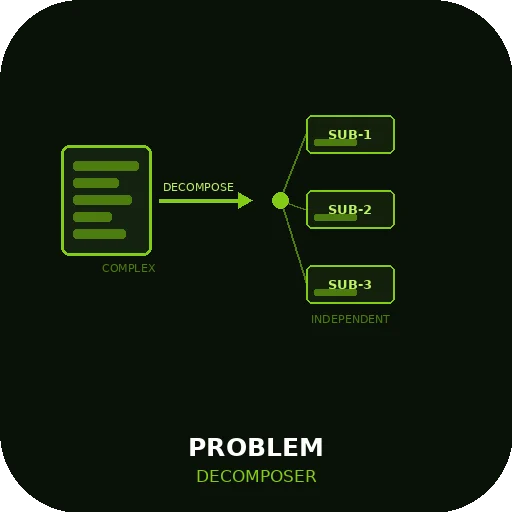
Forces AI agents to identify independent judgment axes before answering any complex question — decomposing the problem into minimum separable sub-problems, solving each one independently, then integrating into a single conclusion so complex analysis is auditable, correctable, and never a blur of mixed reasoning.
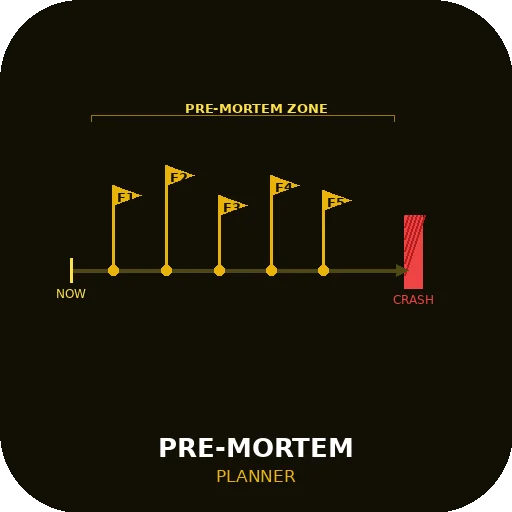
Forces AI agents to enumerate five specific failure scenarios before generating any output — at least one must be unique to the current task — then declare the single most likely failure and its mitigation, so every plan accounts for what could go wrong before committing to what might go right.
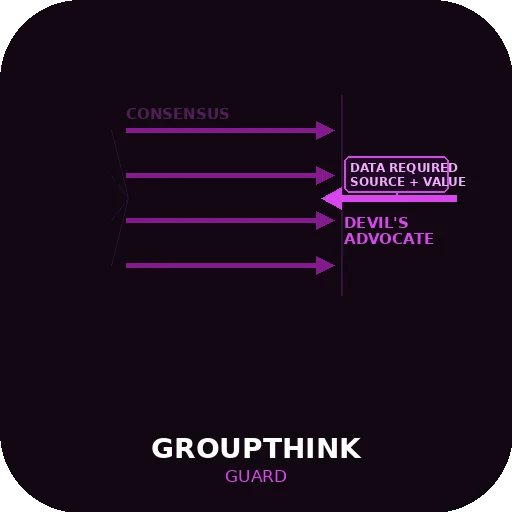
Activates a mandatory devil's advocate role the moment reviewers reach consensus — forcing one party to produce a specific failure scenario backed by data and a source before any conclusion is finalized, so agreement requires evidence, not just alignment.
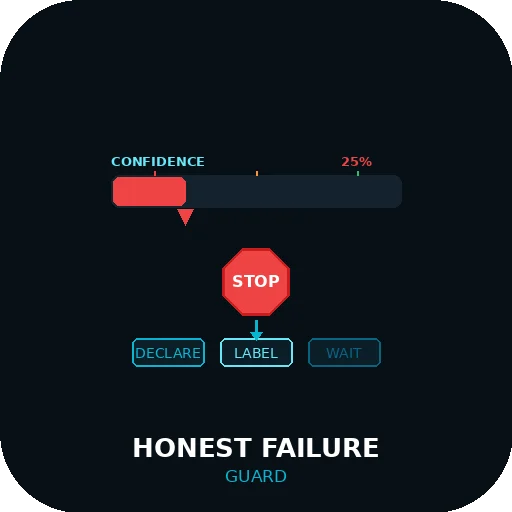
Gives AI agents a structured stop-and-declare protocol for four failure states — low confidence, collapsed premise, exhausted search, and incomplete evidence — so agents label what they don't know instead of fabricating what they can't verify.
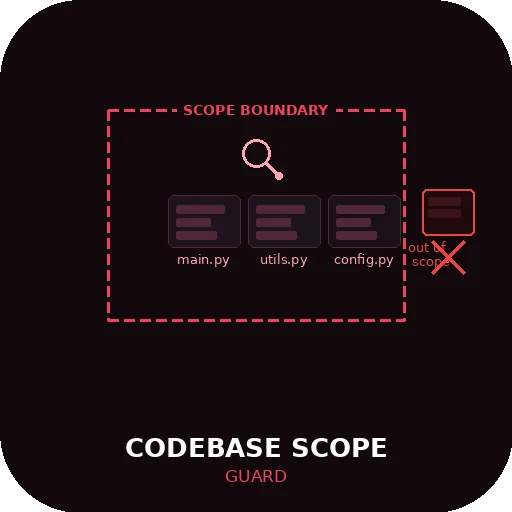
Forces AI coding agents to read exports, callers, and shared utilities before touching any file — then restricts every edit to the declared scope, flags conflicting patterns for human resolution, and reports any file touched outside the boundary.
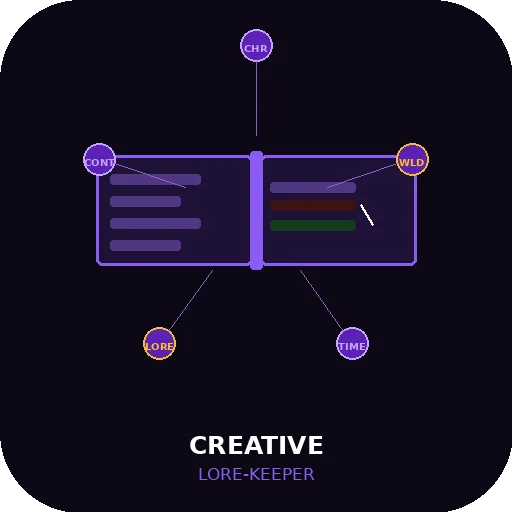
Runs a five-axis consistency check on every turn — verifying character voice, world rules, timeline, dormant lore, and new contradictions — then proactively surfaces unused story elements, so your canon survives from chapter one to the final scene.
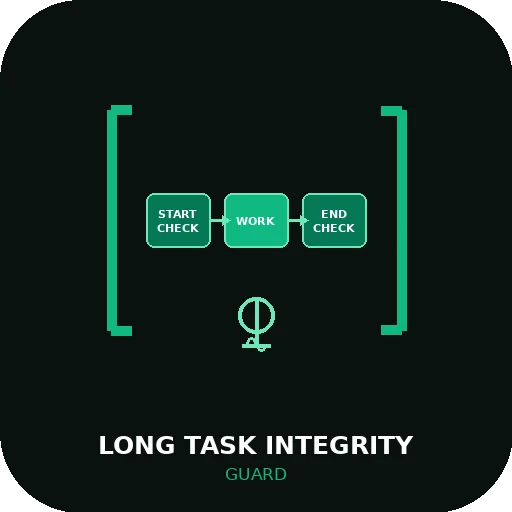
Wraps each phase of a long AI task in a start-check / work / end-check bracket — and re-anchors the original instructions at every phase boundary so the agent cannot drift from its rules or skip verification as the session grows longer.
ポッドキャスト・YouTube・ライブ配信向け台本の提出前品質ゲート。尺ズレ・スポンサー表記ミス・パーソナリティの口調ドリフト・ト書き漏れ・未検証情報を8パターンで検出。日本語標準読速度(320字/分)対応。実際の配信番組制作現場から導出したプロトコル。
Pre-submission quality gate for AI-generated broadcast scripts. Catches timing errors, sponsor name mistakes, host voice drift, missing stage directions, and unverified facts before they reach production. 8 documented failure patterns. Works for podcasts, YouTube, and live broadcast.
Keeps your AI agent from forgetting who it is. Detects and neutralizes persona drift, rule erosion, and prompt injection attempts — across long conversations. Context isolation, anti-drift enforcement, and graceful override responses built in. Your custom persona stays locked.
Forces AI agents to prove a task is actually done before declaring it complete. 4-phase gate: instruction reconciliation, evidence anchoring (values only readable from the actual output), self-scoring (A/B/C/D), and reverse witness check. Eliminates "done" declarations that aren't.
Prevents AI agents from declaring tasks complete until every requirement is verified with a one-line evidence anchor — when a gate fails, the agent stops and reports rather than proceeding, and only a human can unlock the gate to continue.
Forces AI agents to verify every factual claim through live search before output — attaching [SPECULATION] and [UNVERIFIABLE] labels to anything unconfirmed, so fabricated URLs, outdated numbers, and invented citations become visible instead of silent.
Compresses AI filler text — preambles, transitions, repetitions — at 3 intensity levels (Lite / Full / Ultra) while enforcing a protected scope (URLs, numbers, code, reasoning) that is never deleted, so "be concise" stops silently destroying what matters.
Catches cascade failures that partial checks miss — pre-check names the risk before editing, post-check demands evidence values after, then auto-repairs in a loop while rereading the entire file every cycle until zero errors remain.