
Quick Quality Score for Your Draft | ExpertPanel
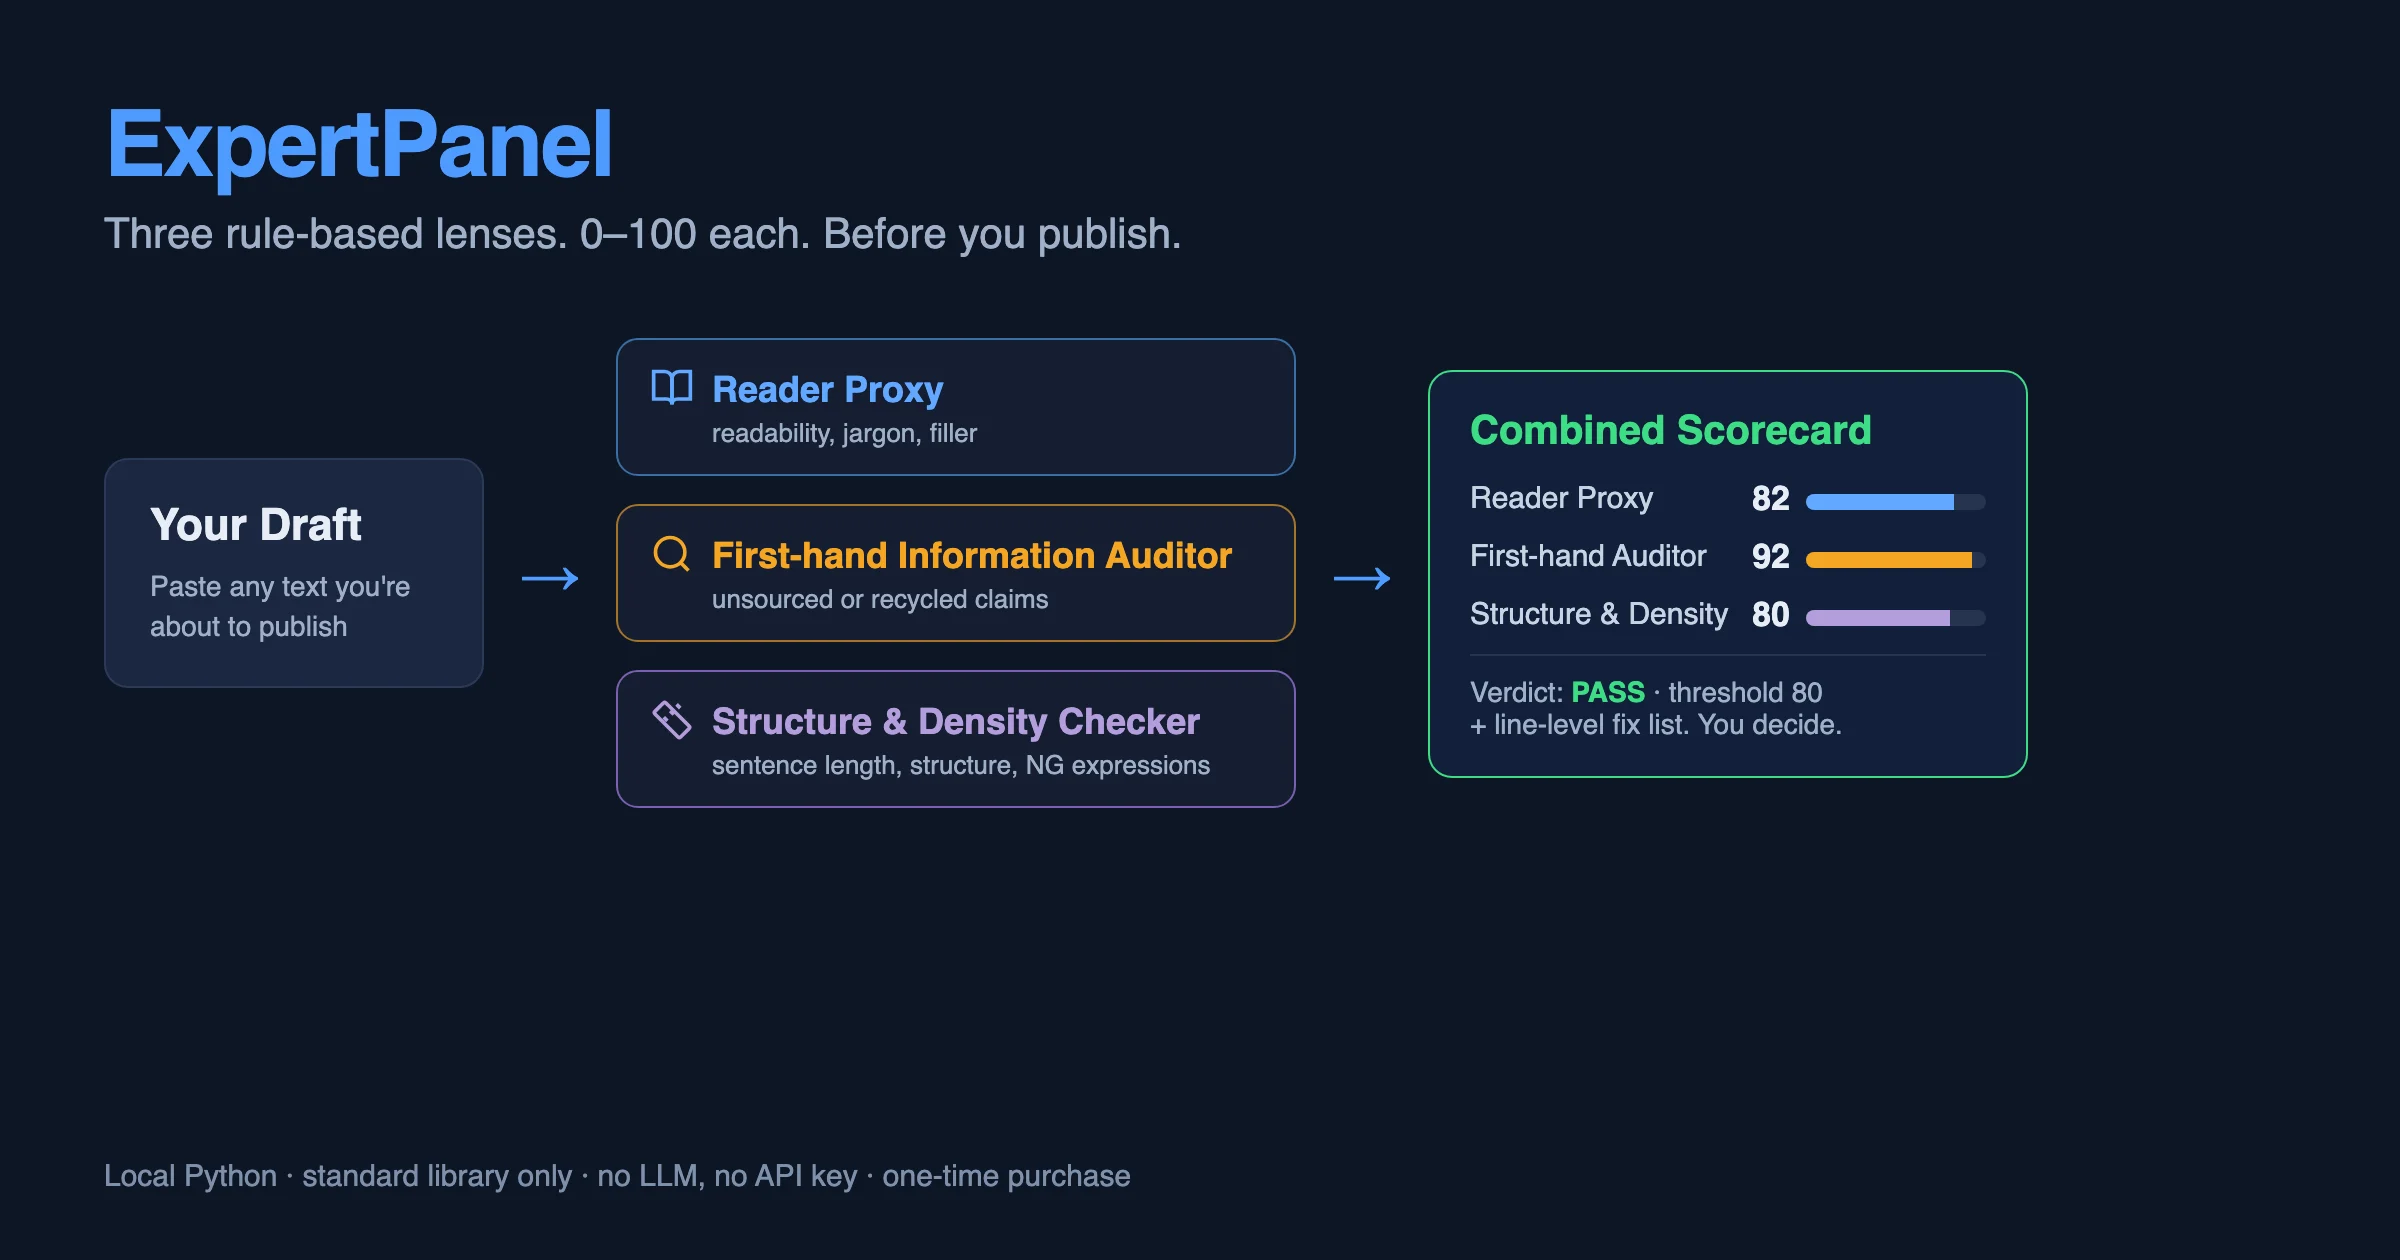
ExpertPanel — A local, rule-based quality gate for your drafts. Three fixed reviewer lenses (Reader Proxy / First-hand Information Auditor / Structure & Density Checker) score your article before you hit publish.
You finished a draft. You feel something is off, but you can no longer see it. ExpertPanel gives you a structured, repeatable second opinion — produced by deterministic rules, not by an AI judgement.
How it works (please read first)
ExpertPanel is a self-contained Python script (Python 3.10+, standard library only). It does NOT call any LLM or external API — not Claude, not GPT, not Gemini. All scoring is deterministic rule-based templating: it measures things like sentence length, jargon and filler density, first-person markers, claims without a source, and NG expressions defined in a style-rules file. Treat the output as a structured checklist / second opinion, not as semantic AI review. The same input always produces the same output.
Who this is for
Anyone about to hit "publish" on a blog post, newsletter, report, or documentation page — and wanting a fast, repeatable, offline quality check instead of vague self-doubt.
What you get back
A combined scorecard (0–100 per lens) and a prioritized, line-level fix list — not a rewrite. You stay in control of every edit.
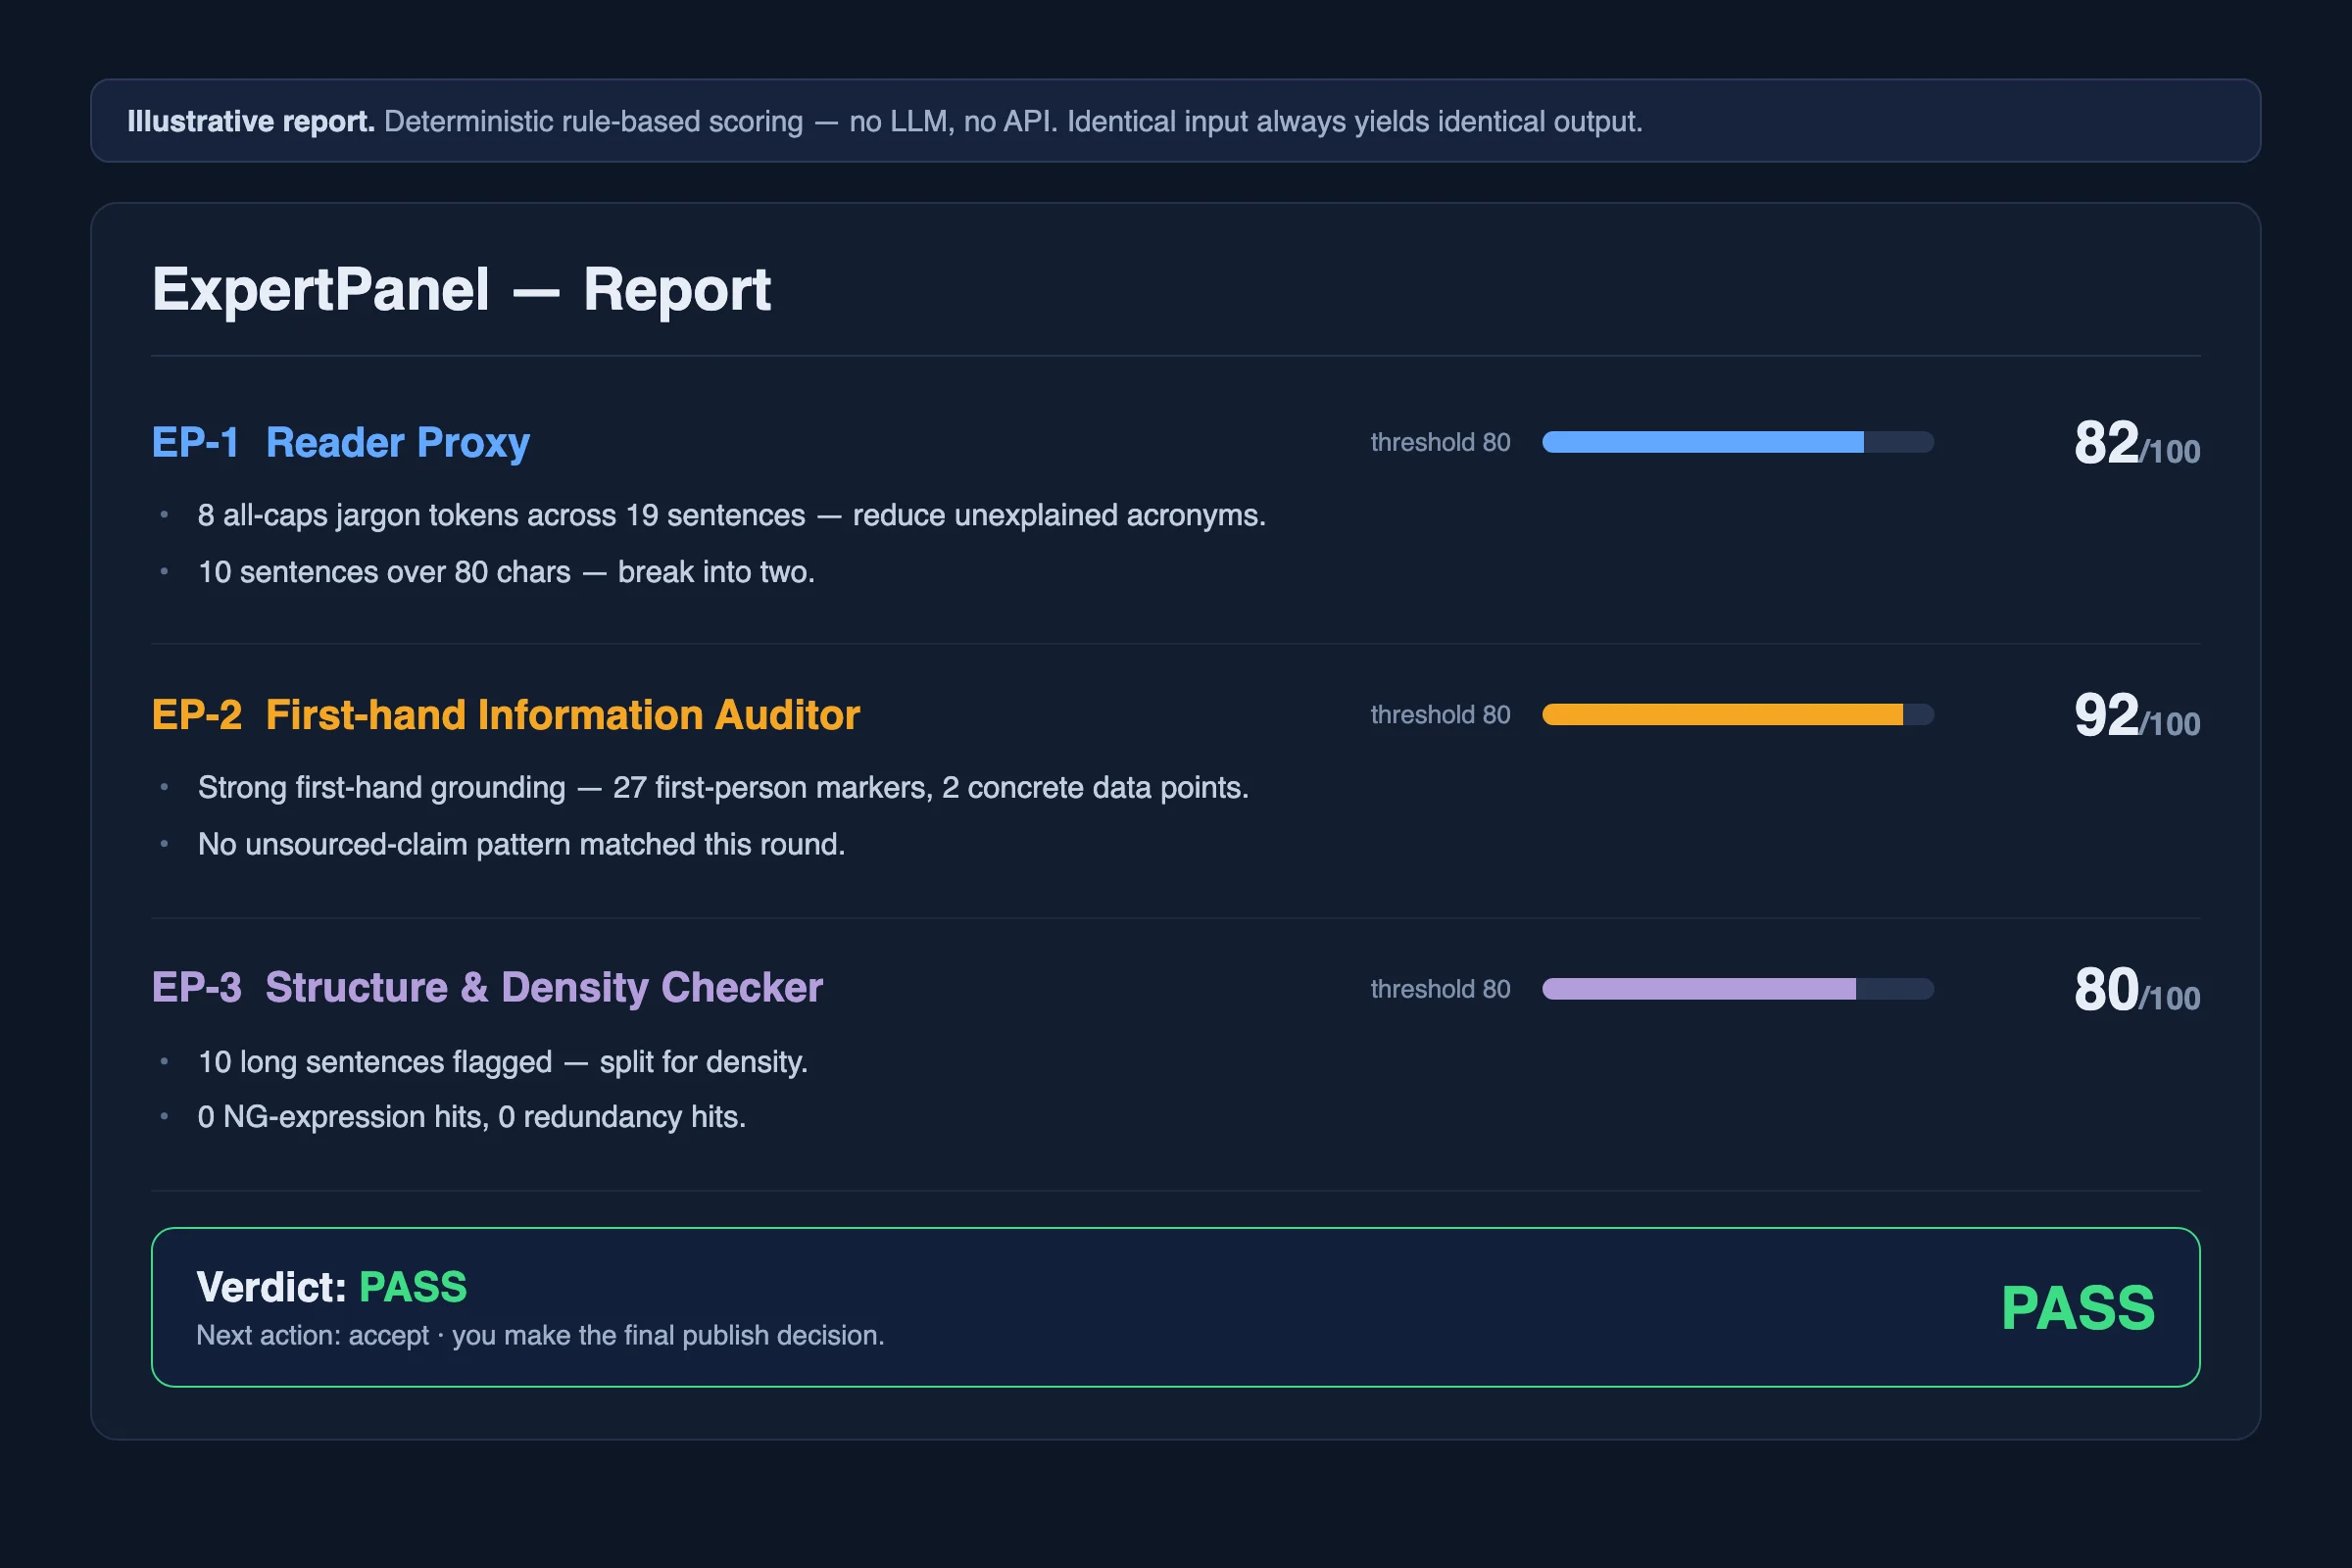
The three reviewer lenses (all rule-based)
• Reader Proxy — flags readability drops, jargon density, and filler phrasing (heuristic).
• First-hand Information Auditor — flags claims with no source and recycled / exaggerated phrasing (heuristic).
• Structure & Density Checker — flags long sentences, NG expressions, and structure-order issues (heuristic).
Each lens scores blind to the others and returns 0–100. Up to 3 re-score rounds, then a final verdict (PASS / REVISION / MAJOR_REVISION / recommend_restructure). You make the final publish decision.
Example: Illustrative output
Note: scores and wording below are illustrative. Flags are pattern/metric based — the script applies fixed rules, so identical input yields identical output. This is not semantic AI analysis.
Input (user pastes a draft excerpt)
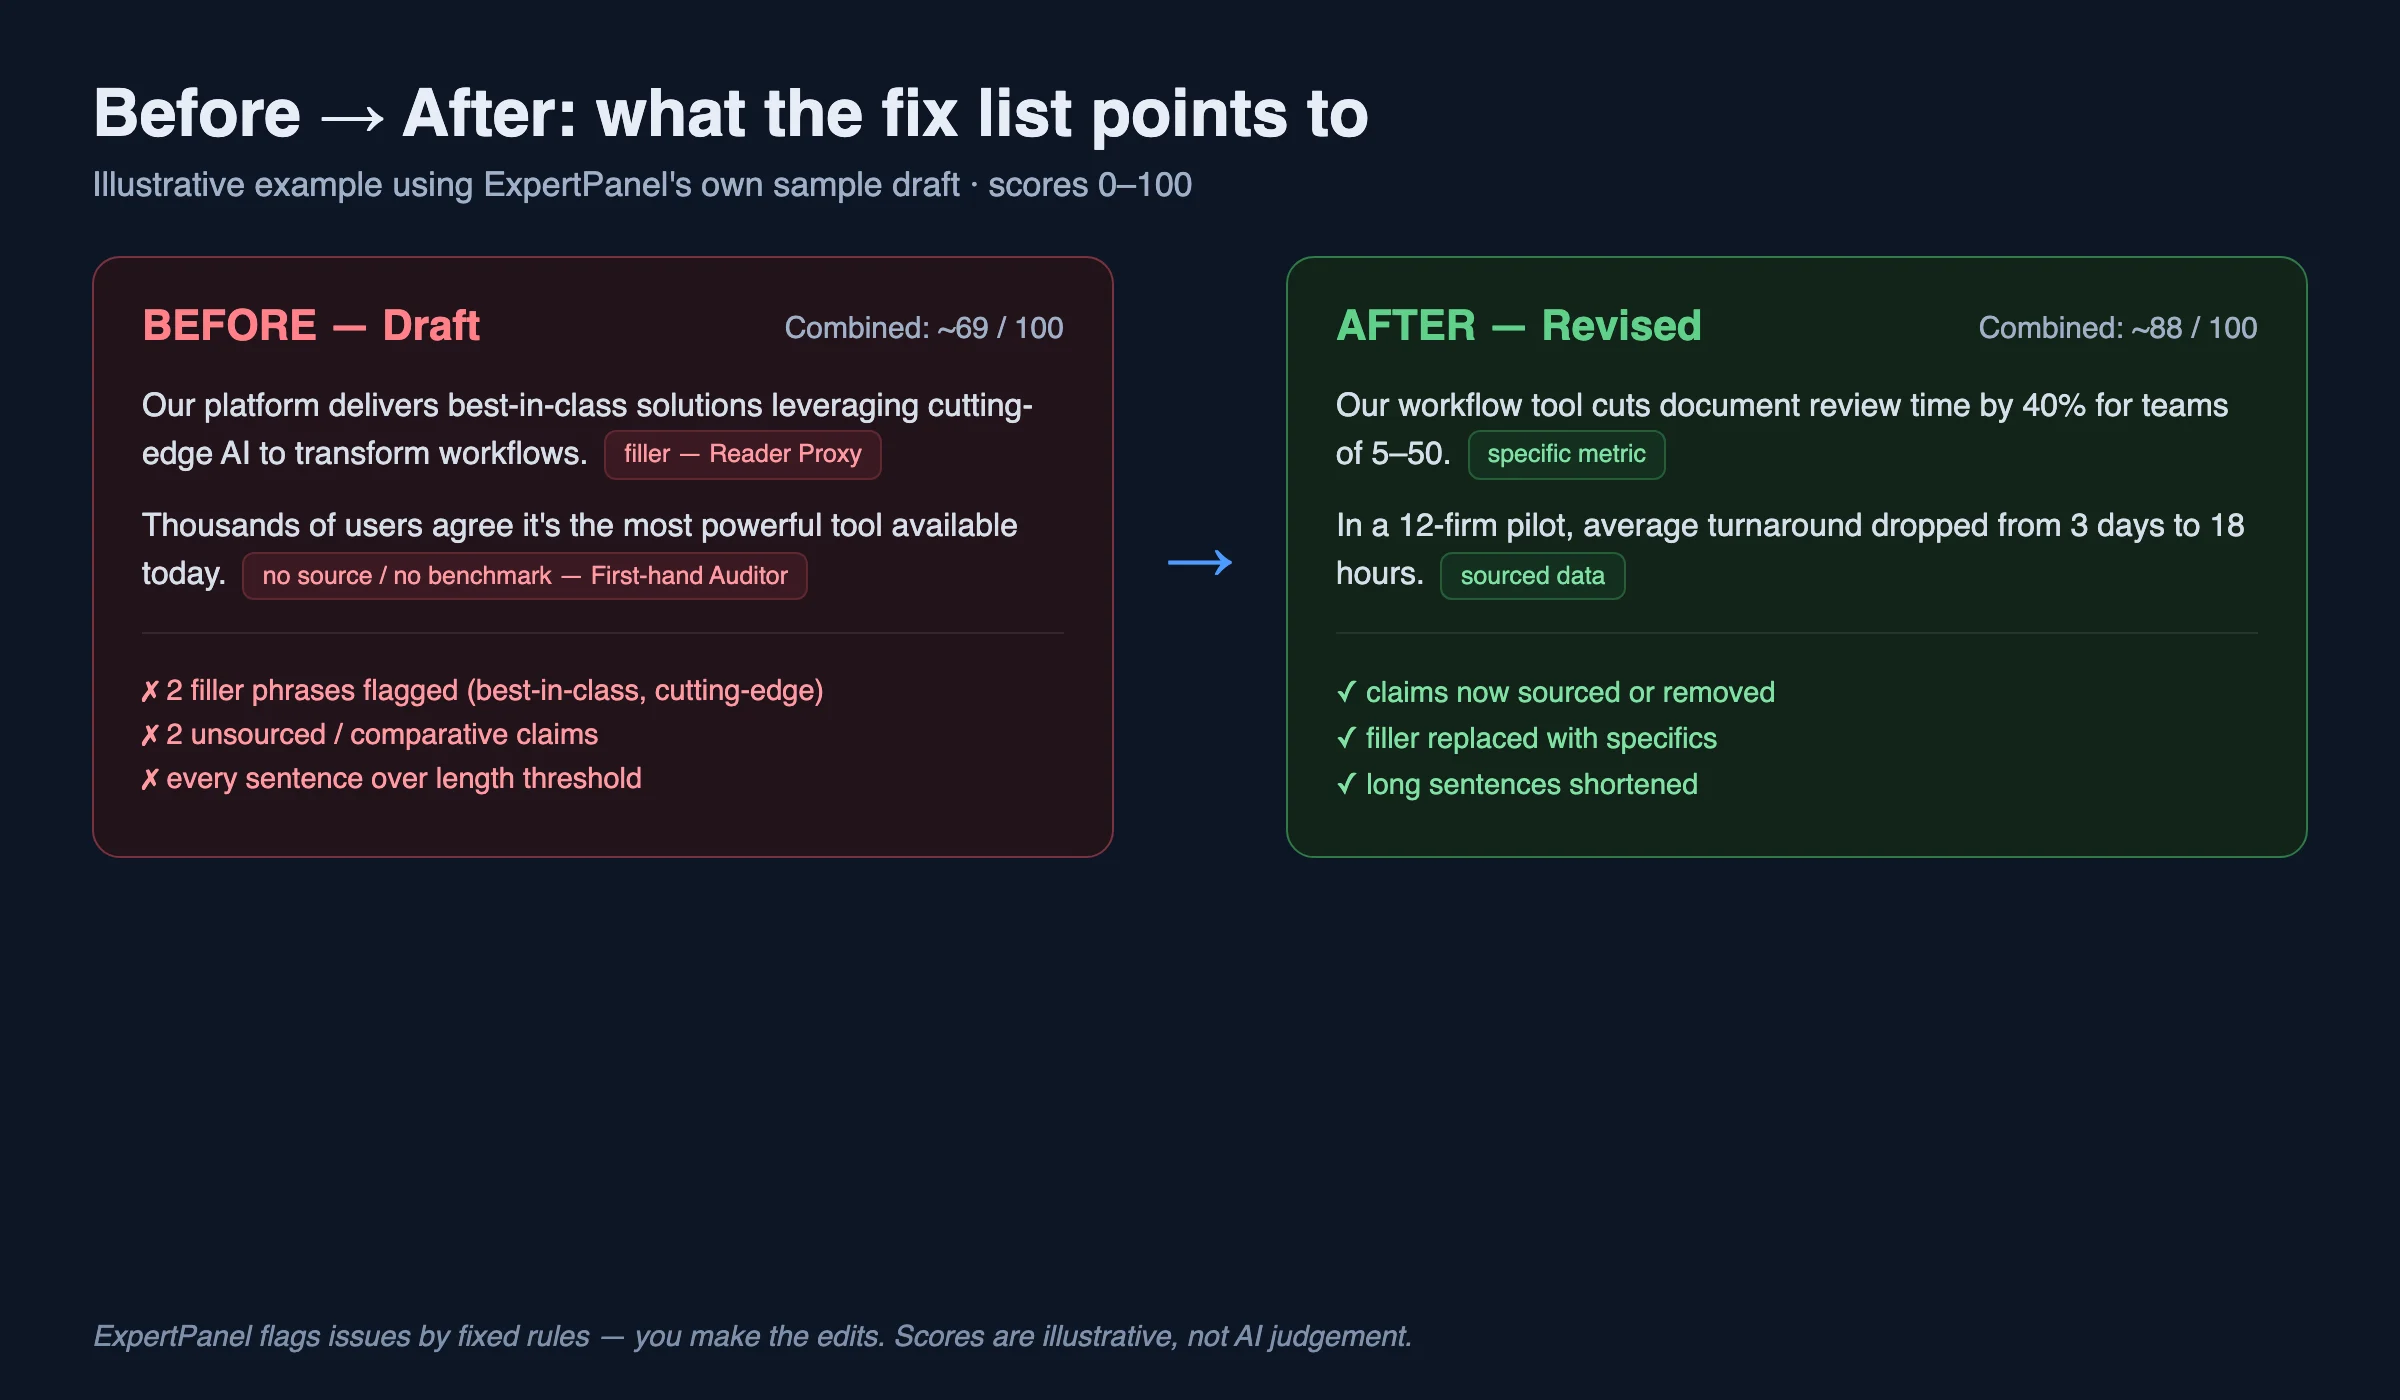
Our platform delivers best-in-class solutions leveraging cutting-edge AI to transform workflows. Thousands of users agree it's the most powerful tool available today.
ExpertPanel output (abbreviated, illustrative)
Reader Proxy (illustrative score: around 70/100)
• Filler-phrase rule matched: "best-in-class", "cutting-edge" — flagged as low-information wording.
• Unverifiable-praise pattern matched: "Thousands of users agree".
First-hand Information Auditor (illustrative score: around 65/100)
• No-source rule matched: "Thousands of users" — no reference detected.
• Comparative-claim rule matched: "most powerful tool available today" — no benchmark detected.
Structure & Density Checker (illustrative score: around 72/100)
• Sentence-length rule: every sentence exceeds the configured length threshold.
• Redundancy rule: "best-in-class" and "most powerful" matched as a duplicate claim type.
• Suggested-rewrite template for Line 1: "[Product] automates [specific task], cutting [specific metric] by [amount]."
Combined (illustrative): around 69 / 100 — priority fixes ordered by lowest-scoring lens: review unsourced claims (First-hand Information Auditor), replace filler phrasing (Reader Proxy), shorten/restructure sentences (Structure & Density Checker).
Why three lenses instead of one score?
A single "looks good" number hides why. ExpertPanel separates the checks so you get a clearer triage:
• Reader Proxy targets reader-facing phrasing the writer can no longer see (curse of knowledge).
• First-hand Information Auditor targets claims with no grounding or source.
• Structure & Density Checker targets long sentences, redundancy, and structure order.
Each lens has its own rule set in config/style_rules.json, so reviews stay consistent across drafts.
Runs fully offline — no LLM, no API keys
• Pure local Python (standard library only) — nothing leaves your machine.
• Does not call Claude, GPT, Gemini, or any external LLM/API.
• One-time purchase — no per-use or per-review charges.
• Customizable via config placeholders and style_rules.json for any content domain.
Setup: download → unzip → run python3 scripts/expert_panel.py --draft your_draft.md --article-type blog.
Works on
• Blog posts & articles
• Newsletters & email campaigns
• Technical documentation
• Reports & white papers
• Social media long-form posts
• Any English prose you are about to publish
日本語サマリー
ExpertPanel は、公開前の原稿を採点する ローカルの Python スクリプト(Python 3.10+・標準ライブラリのみ)です。LLM や外部 API は一切呼び出しません(Claude・GPT・Gemini いずれも不使用)。採点はすべて 決定論的なルールベース で行います(文長・専門用語/冗長表現の密度・一人称マーカー・出典のない主張・NG表現 等の機械的チェック)。3つのレビュー観点(Reader Proxy =読者代理・First-hand Information Auditor =一次情報審査・Structure & Density Checker =構成と密度)が各 0–100 点で採点し、行単位の指摘リストを返します(最大3周・最終判断は利用者)。AI による意味理解ではなく、固定ルールによる構造化チェックのため、同一入力なら同一出力になります。本文中のスコア例は説明用の参考値です。本スキルは買い切りで、追加課金はありません。
Related Reading
How I built a system where AI doesn't stop and ask — it just works:
https://note.com/cute_peony8292/n/nc162eb4864a3

